


OpenAI just changed how it names models, and most people missed why that matters. GPT-5.6 didn’t ship as one model with a dial. It shipped as three separate tiers: Luna, Terra, and Sol. That’s a structural shift, and Sol sits at the top as OpenAI’s new flagship.
OpenAI released GPT-5.6 for general availability on July 9, 2026, following a limited preview that started June 26. Sol scored 53.6 on Agents’ Last Exam, surpassing Claude Fable 5 by 13.1 points, and set a new state-of-the-art score of 80 on the Artificial Analysis Coding Agent Index.
Here’s what we’ll cover:
- What GPT-5.6 Sol actually is and how the new three-tier naming works
- Benchmark performance against competing models
- API pricing, context limits, and token efficiency
- Which ChatGPT plans get access to Sol
- What this release means for AI search visibility and your brand
We track model releases closely at Doc Digital SEM because every change to how ChatGPT reasons and retrieves affects which brands get cited. Our ChatGPT SEO agency services and LLM SEO work exist to keep clients visible as these models evolve.
What GPT-5.6 Sol Actually Is
First, a naming clarification. People search for “ChatGPT 5.6 Sol,” but the model is officially GPT-5.6 Sol. ChatGPT is the product. GPT-5.6 Sol is the model powering it. Same thing in practice, different technically.
The New Three-Tier System
This is the first time OpenAI has given its models names rather than numbers alone. The logic: the number identifies the generation, the name identifies a durable capability tier.
| Model | Position | Built For |
|---|---|---|
| Sol | Flagship | Complex reasoning, agentic coding, cybersecurity, scientific research |
| Terra | Balanced | Everyday production work at roughly half the cost of GPT-5.5 |
| Luna | Fastest, cheapest | High-volume, low-complexity tasks |
OpenAI describes the shift as moving from “one model with a dial” to “three models, choose a tier.” Instead of one model with adjustable reasoning effort, you now pick the tier that matches your task, then set reasoning effort within it.
What Sol Is Designed to Do
OpenAI positions Sol as its strongest model for coding, knowledge work, cybersecurity, and science. Wikipedia’s entry describes it as OpenAI’s “workhorse” and “best coding model yet,” suited for complex reasoning, coding, and agentic workflows.
The specific capabilities that stand out:
- Long-horizon agentic work where the model plans, executes, and verifies across many steps
- Programmatic tool calling that lets the model write and run lightweight programs in memory
- Extended reasoning modes including max and ultra settings
- Cybersecurity applications, which OpenAI calls its strongest defensive security model yet
The Two New Reasoning Settings
Sol ships with two compute settings beyond the standard reasoning effort:
- Max gives the model more time to reason, check its work, and revise outputs before returning them
- Ultra goes further, coordinating multiple agents across parallel workstreams, with the default setup running four agents on separate tracks before synthesizing results
Ultra trades higher token use for stronger results and faster completion on demanding tasks. It’s expensive, and it’s meant for work where correctness matters more than cost.
Benchmark Performance
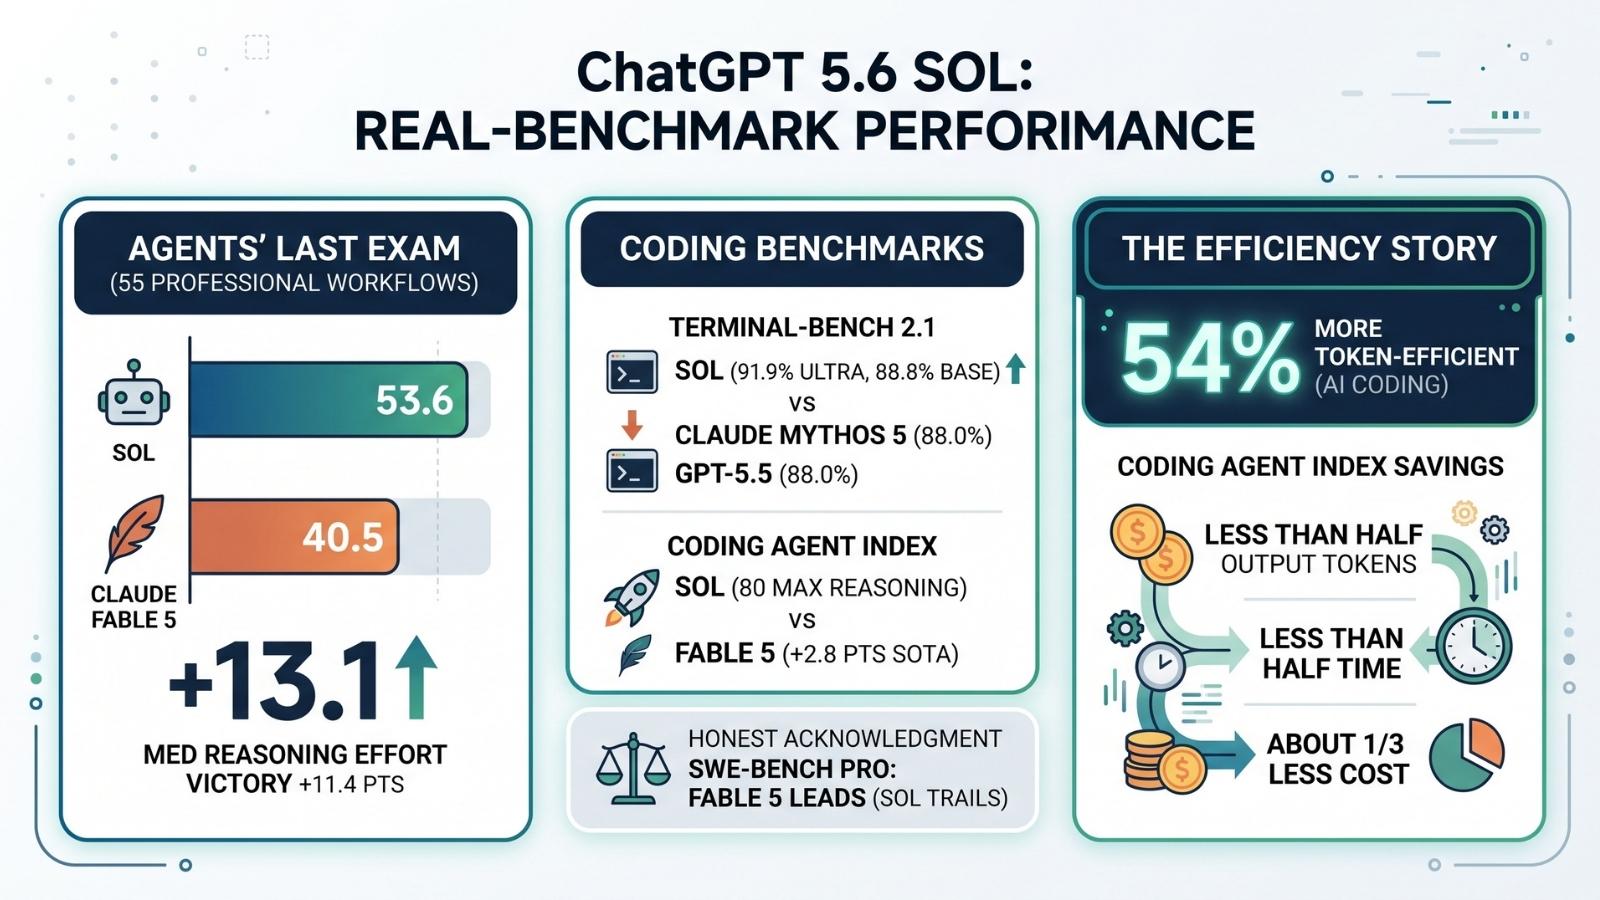
Numbers matter more than marketing language, so here’s where Sol actually lands against competing models.
Agents’ Last Exam
On Agents’ Last Exam, an evaluation spanning 55 professional workflows, GPT-5.6 Sol scored 53.6, surpassing Claude Fable 5 by 13.1 points. Even at medium reasoning effort, it beat Fable 5 by 11.4 points at roughly one-quarter the estimated cost.
Coding Benchmarks
| Benchmark | Sol Performance | Context |
|---|---|---|
| Terminal-Bench 2.1 | 91.9% (ultra), 88.8% (base) | Edges Claude Mythos 5 at 88.0% and GPT-5.5 at 88.0% |
| Coding Agent Index | 80 (max reasoning) | New state of the art, 2.8 points above Fable 5 |
| SWE-Bench Pro | Trails | Claude Fable 5 leads this benchmark by a notable margin |
Worth being honest about that last row. Sol doesn’t sweep every benchmark. Sol leads the Coding Agent Index and Terminal-Bench 2.1, but Claude holds ground on SWE-Bench Pro. Different benchmarks measure different things, and no single model dominates all of them.
The Efficiency Story
This is arguably the bigger headline than raw capability. OpenAI CEO Sam Altman noted that Sol is 54% more token-efficient for AI coding tasks compared to previous versions.
On the Coding Agent Index, Sol used less than half the output tokens, took less than half the time, and cost about one-third less than its closest competitor.
Why efficiency matters more than it sounds: at scale, total tokens drive your bill. A model that scores marginally higher while burning three times the tokens is worse in production, not better.
API Pricing and Context Limits
If you’re building on the OpenAI API rather than using ChatGPT directly, here’s what Sol costs.
GPT-5.6 Family Pricing
| Model | Input (per 1M tokens) | Output (per 1M tokens) |
|---|---|---|
| Sol | $5 | $30 |
| Terra | $2.50 | $15 |
| Luna | $1 | $6 |
Caching and Long-Context Rates
Two details that meaningfully affect real-world cost:
- Cache reads receive a 90% discount, which makes prompt caching essential for any repeated-context workload
- Cache writes cost 1.25x the standard input rate
- Requests over 272K tokens incur higher long-context rates
If you’re running agents with large system prompts or repeated document context, prompt caching is where the savings live. Ignoring it can multiply your bill several times over for identical output.
Context Window
Sol reportedly supports a context window around 1.05M tokens with up to 128,000 output tokens. That’s enough to hold entire codebases, long document sets, or extended agent traces in a single request.
Which ChatGPT Plans Get Sol
Access depends on your ChatGPT plan. Here’s how it breaks down.
Plan Access
Plus, Pro, Business, and Enterprise users can choose among GPT-5.6 Sol, Terra, and Luna and set an effort level for each.
| Plan | Sol Access | Notes |
|---|---|---|
| Free | Limited or routed | Typically defaults to lower tiers |
| Plus | Yes, with usage limits | Standard usage caps apply |
| Pro | Yes, expanded limits | Access to higher reasoning options |
| Business | Yes, included | Managed through workspace settings |
| Enterprise | Yes, included | Admin-controlled model availability |
Where to Find It
Sol appears in the model picker across the web interface, the ChatGPT desktop app, and mobile. For Business and Enterprise accounts, admins control which models appear for their users through workspace settings.
Extra high reasoning options and ultra mode are gated to eligible paid plans, since the compute cost per request is substantially higher than standard ChatGPT conversations.
Rollout Timing
OpenAI rolled out GPT-5.6 across ChatGPT, Codex, and the API globally, with full availability expected within roughly 24 hours of launch.
There’s a regulatory wrinkle worth knowing. Due to U.S. government restrictions, GPT-5.6 was first released as a limited preview on June 26, 2026, for a small group of trusted partners before general availability on July 9. The preview period reflects the increasing regulatory attention frontier models now receive, which is a pattern likely to continue.
What This Means for AI Search Visibility
Here’s the part most coverage skips, and the part that actually affects your business.
Better Reasoning Changes What Gets Cited
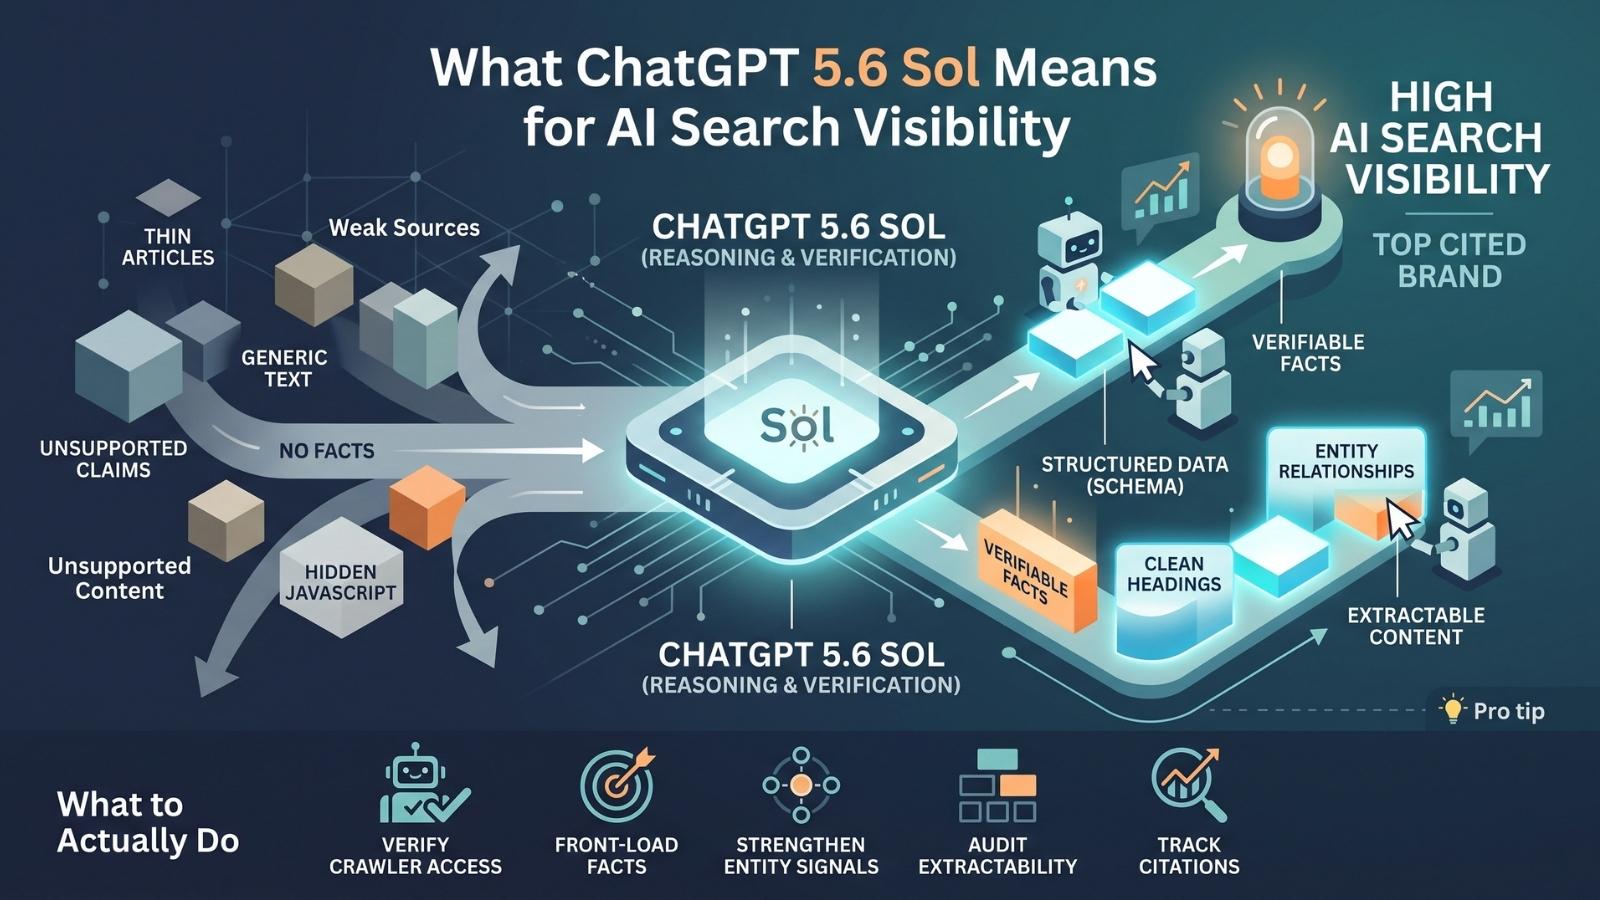
Every model upgrade shifts how ChatGPT evaluates and cites sources. Sol reasons longer, verifies more carefully, and inspects intermediate results before returning answers. That has a direct consequence for brands:
- Weak sources get filtered harder. A model that verifies its work is less likely to cite thin, unsupported content.
- Specific, verifiable facts win. Sol’s emphasis on reducing hallucinations in high-stakes tasks means it favors content it can confirm.
- Structured content gets extracted more reliably. Better parsing means clean formatting matters even more, not less.
The Agentic Shift Is Accelerating
Sol’s ultra mode coordinating four agents in parallel isn’t a consumer feature. It’s a signal about where AI is heading: models that browse, evaluate, compare, and act autonomously.
For brands, that means your website increasingly needs to be readable by machines, not just people. Agents don’t render JavaScript reliably. They don’t admire your design. They extract facts, compare options, and move on.
We covered this shift in depth in our breakdown on agent-based search, and Sol’s release makes that timeline more urgent, not less.
What to Actually Do About It
Concrete actions that matter given how Sol behaves:
- Verify AI crawler access. Confirm GPTBot and OAI-SearchBot aren’t blocked in your robots.txt.
- Front-load verifiable facts. Lead every important page with specific, checkable claims rather than positioning language.
- Strengthen entity signals. Sol reasons across entity relationships. Clear schema markup and consistent brand data make you easier to cite confidently.
- Audit for extractability. Clean headings, tables, FAQ blocks, and structured content get pulled into answers. Walls of prose don’t.
- Track your citations. Test how Sol describes your brand versus how GPT-5.5 did. Model changes shift citation patterns.
That last point matters more than people realize. A model upgrade can quietly change which brands appear in AI answers across your entire category. If you’re not testing, you won’t notice until traffic moves.
💡 Pro tip: Run your top 20 buyer questions through ChatGPT with Sol selected and document which brands get cited. Compare against results from three months ago. That single exercise reveals more about your AI visibility than most analytics dashboards.
Our LLM SEO services and AI SEO agency work include exactly this kind of monitoring, because staying visible through model transitions is now a permanent part of the job.
How Sol Works Inside ChatGPT
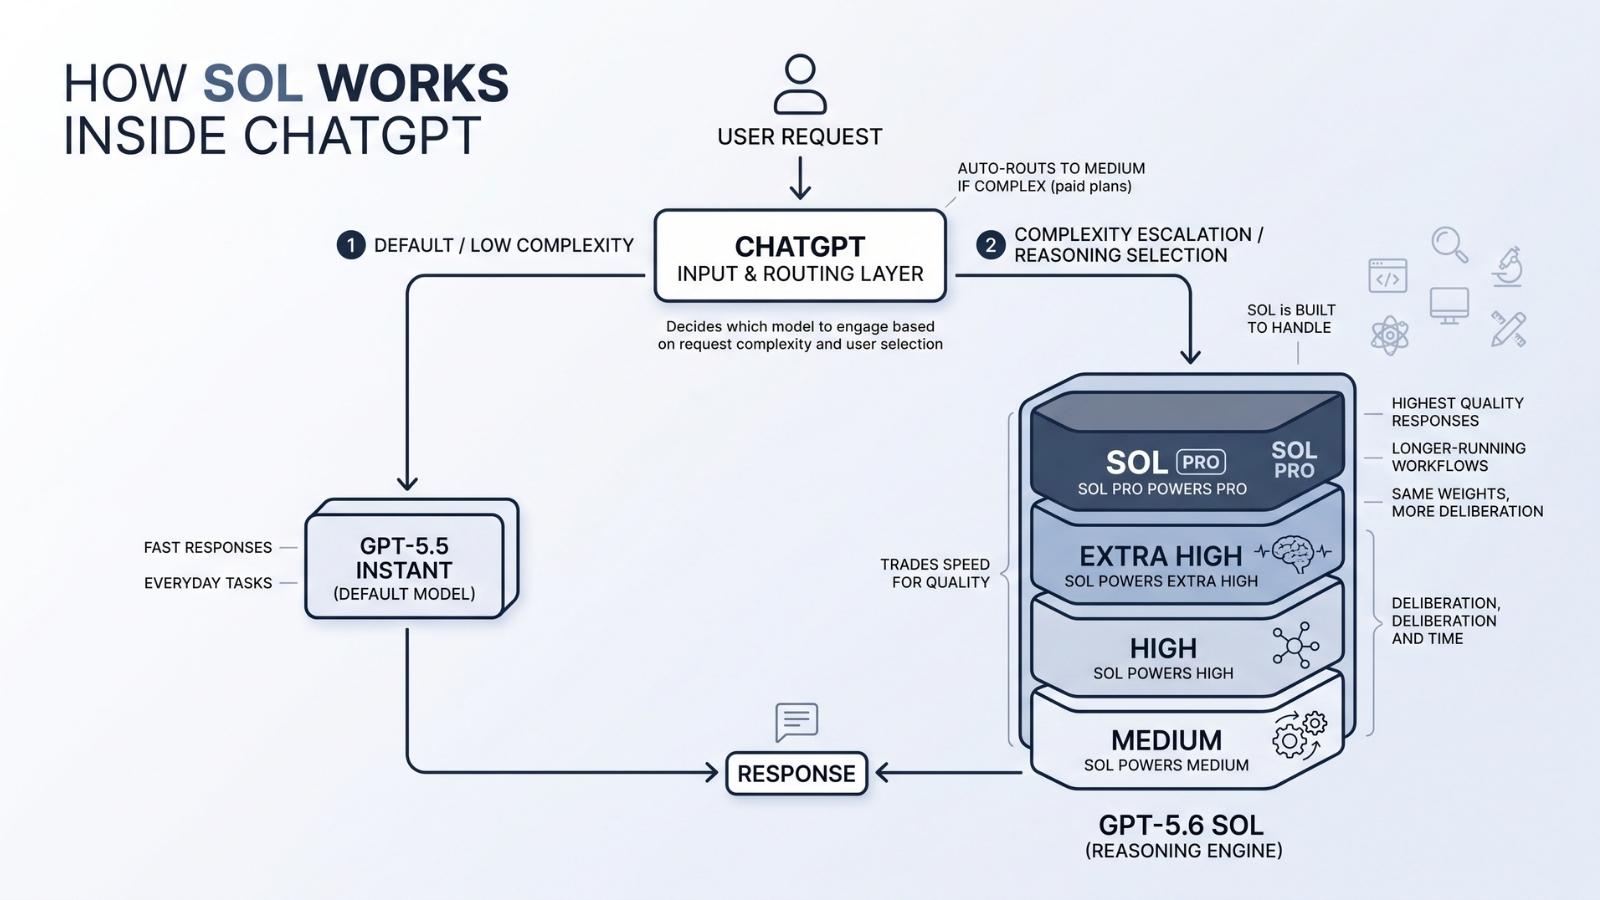
Benchmarks tell you what a model can do in a lab. Understanding how Sol is actually wired into ChatGPT tells you what you’ll experience day to day. The setup is more layered than most people expect.
GPT-5.5 Instant Is Still the Default Model
This surprises people. Sol didn’t replace everything. GPT-5.5 Instant remains the default model for fast, everyday responses. Sol activates when you select a higher reasoning level, or when ChatGPT automatically escalates a complex request.
On eligible paid plans, ChatGPT can automatically route complex requests to more reasoning. In the model picker, this shows up as Instant switching to Medium. You can toggle that automatic switching on or off under Configure in the model picker.
The Reasoning Levels Explained
Here’s the piece that confuses most users. Sol doesn’t appear in the picker as “Sol.” It appears as reasoning levels.
| Picker Option | What Powers It |
|---|---|
| Instant | GPT-5.5 Instant (default, fast responses) |
| Medium | GPT-5.6 Sol |
| High | GPT-5.6 Sol |
| Extra High | GPT-5.6 Sol, highest standard reasoning effort |
| Pro | GPT-5.6 Sol Pro |
GPT-5.6 Sol powers the Medium, High, and Extra High reasoning options on eligible plans, while Sol Pro powers the Pro option.
What Sol Pro Actually Is
Worth clearing up a common misunderstanding: Sol Pro is not a separate model. It’s the same underlying Sol served with reasoning.mode set to pro, producing higher-quality responses on difficult tasks and longer-running workflows.
Same weights, more deliberation. Sol Pro is available to Pro and Enterprise users in the model picker.
Where Each Model Shows Up
Availability varies by surface, and the pattern is worth noticing:
- Standard ChatGPT conversations: Sol is available from Plus upward. Terra and Luna aren’t selectable here. Logged-out users don’t get Sol at all.
- ChatGPT Work and Codex: Free and Go users access Terra. Paid users choose among all three tiers and set effort per model.
- API: All three tiers available to developers, with Programmatic Tool Calling and multi-agent features in the Responses API.
That last detail is a quiet signal about product strategy. The cheapest guaranteed path to GPT-5.6 isn’t the chat surface. It’s ChatGPT Work and Codex, where free and Go users get Terra access.
Business and Enterprise Controls
For managed workspaces, admins control which models appear for their users through workspace settings. Sol access is included for Business and Enterprise plans, but individual availability depends on how your workspace is configured.
If Sol isn’t showing in your picker on a business account, that’s usually an admin setting rather than a plan limitation.
What Sol Is Built to Handle
OpenAI designed Sol for complex work across six specific domains:
- Coding and agentic development workflows
- Knowledge work and research
- Cybersecurity, where OpenAI calls it their strongest defensive model
- Science and technical research
- Computer use, meaning agentic control of software interfaces
- Design and creative work
That computer use capability matters more than it sounds. It’s the foundation for agents that operate software the way a person would, clicking, typing, navigating, and verifying results.
Programmatic Tool Calling and the Hosted Runtime
One genuinely new developer capability: Programmatic Tool Calling lets the model write and execute lightweight programs during a task rather than routing every intermediate result back through the model.
The execution happens in an isolated V8 runtime with no network access. That sandboxed hosted runtime is what makes the feature safe to ship, and it’s a meaningful efficiency gain. Instead of burning tokens shuttling data back and forth, Sol filters intermediate results in code and only surfaces what matters.
For developers building agents, this is where a lot of the 54% token efficiency improvement comes from.
Usage Limits and Speed Trade-offs
Every reasoning level trades speed for quality:
- Instant returns in seconds, handles everyday questions
- Medium adds noticeable latency, handles most professional work
- High and Extra High take substantially longer, worth it for genuinely complex tasks
- Pro runs longest, built for problems where verification matters more than turnaround
Usage limits apply per plan and can shift based on system conditions, market, and abuse-prevention guardrails. Free-tier limits reset within rolling windows rather than daily.
💡 Pro tip: Don’t default to the highest reasoning level for everything. Extra High on a simple question wastes your usage allowance and returns a slower answer that isn’t meaningfully better. Match the reasoning effort to the actual difficulty of the task.
One Honest Note on the Benchmarks
Since we cited benchmark figures earlier, a caveat worth including for credibility. OpenAI’s announcement prose claims a new high of 53.6 on Agents’ Last Exam, while its own eval table lists Sol at 52.7%. The higher figure reflects a maxed-out reasoning configuration rather than standard settings.
Similarly, on SWE-Bench Pro, Sol’s 64.6% trails Claude Mythos 5’s 80.3% by roughly 15 points. Sol leads on agentic coding benchmarks and loses on others. Any source telling you one model wins everything isn’t reading the tables carefully.
Stay Visible Through Every Model Update With Doc Digital SEM
GPT-5.6 Sol is a meaningful step forward, particularly on efficiency and agentic work. But the more important story for businesses isn’t the benchmark scores. It’s that every model release reshuffles which brands AI recommends.
Here’s what to remember:
- GPT-5.6 ships as three tiers: Sol (flagship), Terra (balanced), Luna (cheapest)
- Sol scored 53.6 on Agents’ Last Exam and 80 on the Coding Agent Index
- API pricing runs $5 input / $30 output per million tokens, with 90% cache read discounts
- Plus, Pro, Business, and Enterprise plans all include Sol access
- Ultra mode coordinates four parallel agents for demanding tasks
- Better reasoning means weaker sources get filtered harder in AI answers
Every model upgrade changes which brands ChatGPT cites. Doc Digital SEM keeps clients visible through those shifts. Get your free AI visibility audit (valued at $1,500) or explore our ChatGPT SEO services and find out how Sol describes your brand today.
FAQs
What is GPT-5.6 Sol?
GPT-5.6 Sol is OpenAI’s flagship model, released July 9, 2026. It leads the GPT-5.6 family alongside Terra and Luna, built for complex reasoning, coding, and agentic workflows.
What are the 5 things you shouldn’t tell ChatGPT?
Avoid sharing passwords, financial account details, medical records, confidential business information, and personally identifiable data about others. Standard conversations may be reviewed to improve models.
Why are people leaving ChatGPT?
Some users switch for pricing, specific capabilities, or privacy preferences. Competing models lead on certain benchmarks, so choice often comes down to task fit rather than overall quality.
What does ChatGPT stand for?
ChatGPT stands for Chat Generative Pre-trained Transformer. “Generative” means it produces text, “pre-trained” refers to its training process, and “transformer” is the underlying model architecture.
How much does GPT-5.6 Sol cost?
API pricing is $5 per million input tokens and $30 per million output tokens. Cache reads receive a 90% discount. ChatGPT Plus, Pro, Business, and Enterprise plans include Sol access.
Is Sol better than Claude?
It depends on the task. Sol leads Terminal-Bench 2.1 and the Coding Agent Index, while Claude Fable 5 leads SWE-Bench Pro. Neither model dominates every benchmark.


