


If your brand keeps getting skipped in AI generated answers, the problem usually isn’t your content. It’s your entities. AI search platforms like ChatGPT, Gemini, Perplexity, Claude, and Google AI Overviews don’t just read your pages. They recognize entities, link them to knowledge graphs, and use those connections to decide which brands to cite. Miss any step in that chain, and you’re invisible.
AI-search interactions now represent 30% of total search volume, and click-through rates for queries featuring AI summaries have fallen by as much as 61% since mid-2024. The brands winning this new layer aren’t ranking higher. They’re being recognized better.
Here’s what we’ll discuss:
- The glossary: entities, NER vs. entity linking, and the role of knowledge graphs
- How generative AI search engines actually work, step by step
- Why does entity recognition affect AI search visibility
- A hands-on workflow for entity recognition, linking, and knowledge graph exploration
- The complete relevance engineering playbook for entities and AI search
This is the technical layer Doc Digital SEM ships into every client engagement. Through our LLM SEO services and GEO agency work, we engineer the entity signals that make AI systems recognize, trust, and cite our clients across every platform that matters.
The Glossary: Entities, NER, Linking, and Knowledge Graphs
Before we get into how AI search platforms leverage entity recognition, you need a clean working vocabulary. These four terms get used interchangeably online, and that confusion is exactly why most SEO teams implement entity work half-heartedly. Let’s fix that.
What Is an Entity?
An entity is a distinct real-world thing. A person, a product, a place, an organization, an event, a concept. Entities exist independently of the words used to describe them.
For example:
- “Nike” is an Organization entity
- “Air Force One” is a Product entity
- “Tokyo” is a Location entity
- “World War II” is an Event entity
A search query like “shop online Nike Air Force One” contains entity references, but the query itself is just keywords with intent. The entities are Nike (brand) and Air Force One (product). That distinction matters because AI systems retrieve, reason, and cite at the entity level, not the keyword level.
Each entity has attributes (defining properties) and variables (specific values). For example, the entity “Air Force One” has the attribute “color,” with variables like “white,” “black,” or “red.” This structure is the EAV model (Entity, Attribute, Variable), and it’s the foundation of a scalable entity-based content strategy.
Named Entity Recognition (NER)
Named Entity Recognition is the natural language processing process of scanning unstructured text and extracting named entities. NER software classifies the entities it identifies into predefined categories: Person, Organization, Product, Location, Date, Monetary Values, and so on.
Modern NER uses a mix of approaches:
- Machine learning algorithms trained on labeled data
- Deep learning models, including recurrent neural networks and transformers
- Conditional random fields for sequential entity classification
- Rule based methods and rule based systems for domain-specific entities (legal documents, medical research, etc.)
The output of NER is structured information extracted from unstructured text. A blog post becomes a list of identified entities with types, locations, and confidence scores. That structured output is what AI systems can actually reason about.
Entity Linking (EL)
Entity recognition is the first step. Entity linking is the second, and it’s where the real magic happens.
Entity linking takes each detected entity from your text and maps it to a canonical entity ID inside a knowledge base. Think Wikidata Q-IDs (Q312 for Apple Inc.) or Google’s Knowledge Graph machine IDs (MIDs).
Why this matters:
- Disambiguation. “Jordan” could be a person, a country, or a sneaker. Entity linking resolves which one based on the surrounding words.
- Synonym consolidation. “NYC,” “New York,” and “New York City” all collapse to the same canonical ID.
- Cross-language consistency. A single canonical ID represents one entity regardless of language.
- Better tracking. You can count every mention of an entity, not just exact keyword matches.
Without entity linking, two pages mentioning the same brand in different ways look like unrelated content to AI systems. With entity linking, both pages reinforce the same entity in the model’s understanding.
The Role of Knowledge Graphs
A knowledge graph is a structured database that maps entities and the relationships between them. AI search systems use knowledge graphs to:
- Validate entities they identify in your content
- Disambiguate ambiguous mentions using contextual signals
- Enrich responses with verified attributes (founding date, headquarters, products)
- Connect related entities through known relationships
The major knowledge graphs powering AI search:
- Public graphs: Wikidata, Freebase, DBpedia (broad coverage)
- Proprietary graphs: Google’s Knowledge Graph, Bing’s Satori, Microsoft Academic Graph
- Vertical taxonomies: ICD and SNOMED for healthcare, GS1 for commerce, GeoNames for places, OpenAlex for research
When your site links its entities to public IDs through schema markup (sameAs, @id, organization identifiers), AI search systems can disambiguate your brand, consolidate related pages, and confidently surface your content in AI generated summaries.
NER vs. Entity Linking, Side by Side
| Process | What It Does | Output |
|---|---|---|
| NER | Identifies entities in text and assigns broad types | “Apple → Organization” |
| Entity Linking | Maps each entity mention to a unique knowledge graph ID | “Apple → Q312 (Apple Inc., Wikidata)” |
NER tells you what type of thing you’re looking at. Entity linking tells you exactly which thing. Both are required for AI systems to confidently recognize and cite your brand.
For a deeper read on the broader entity ecosystem, our breakdown on structured data for LLM optimization covers the schema layer that makes entity linking possible at scale.
How Generative AI Search Actually Works
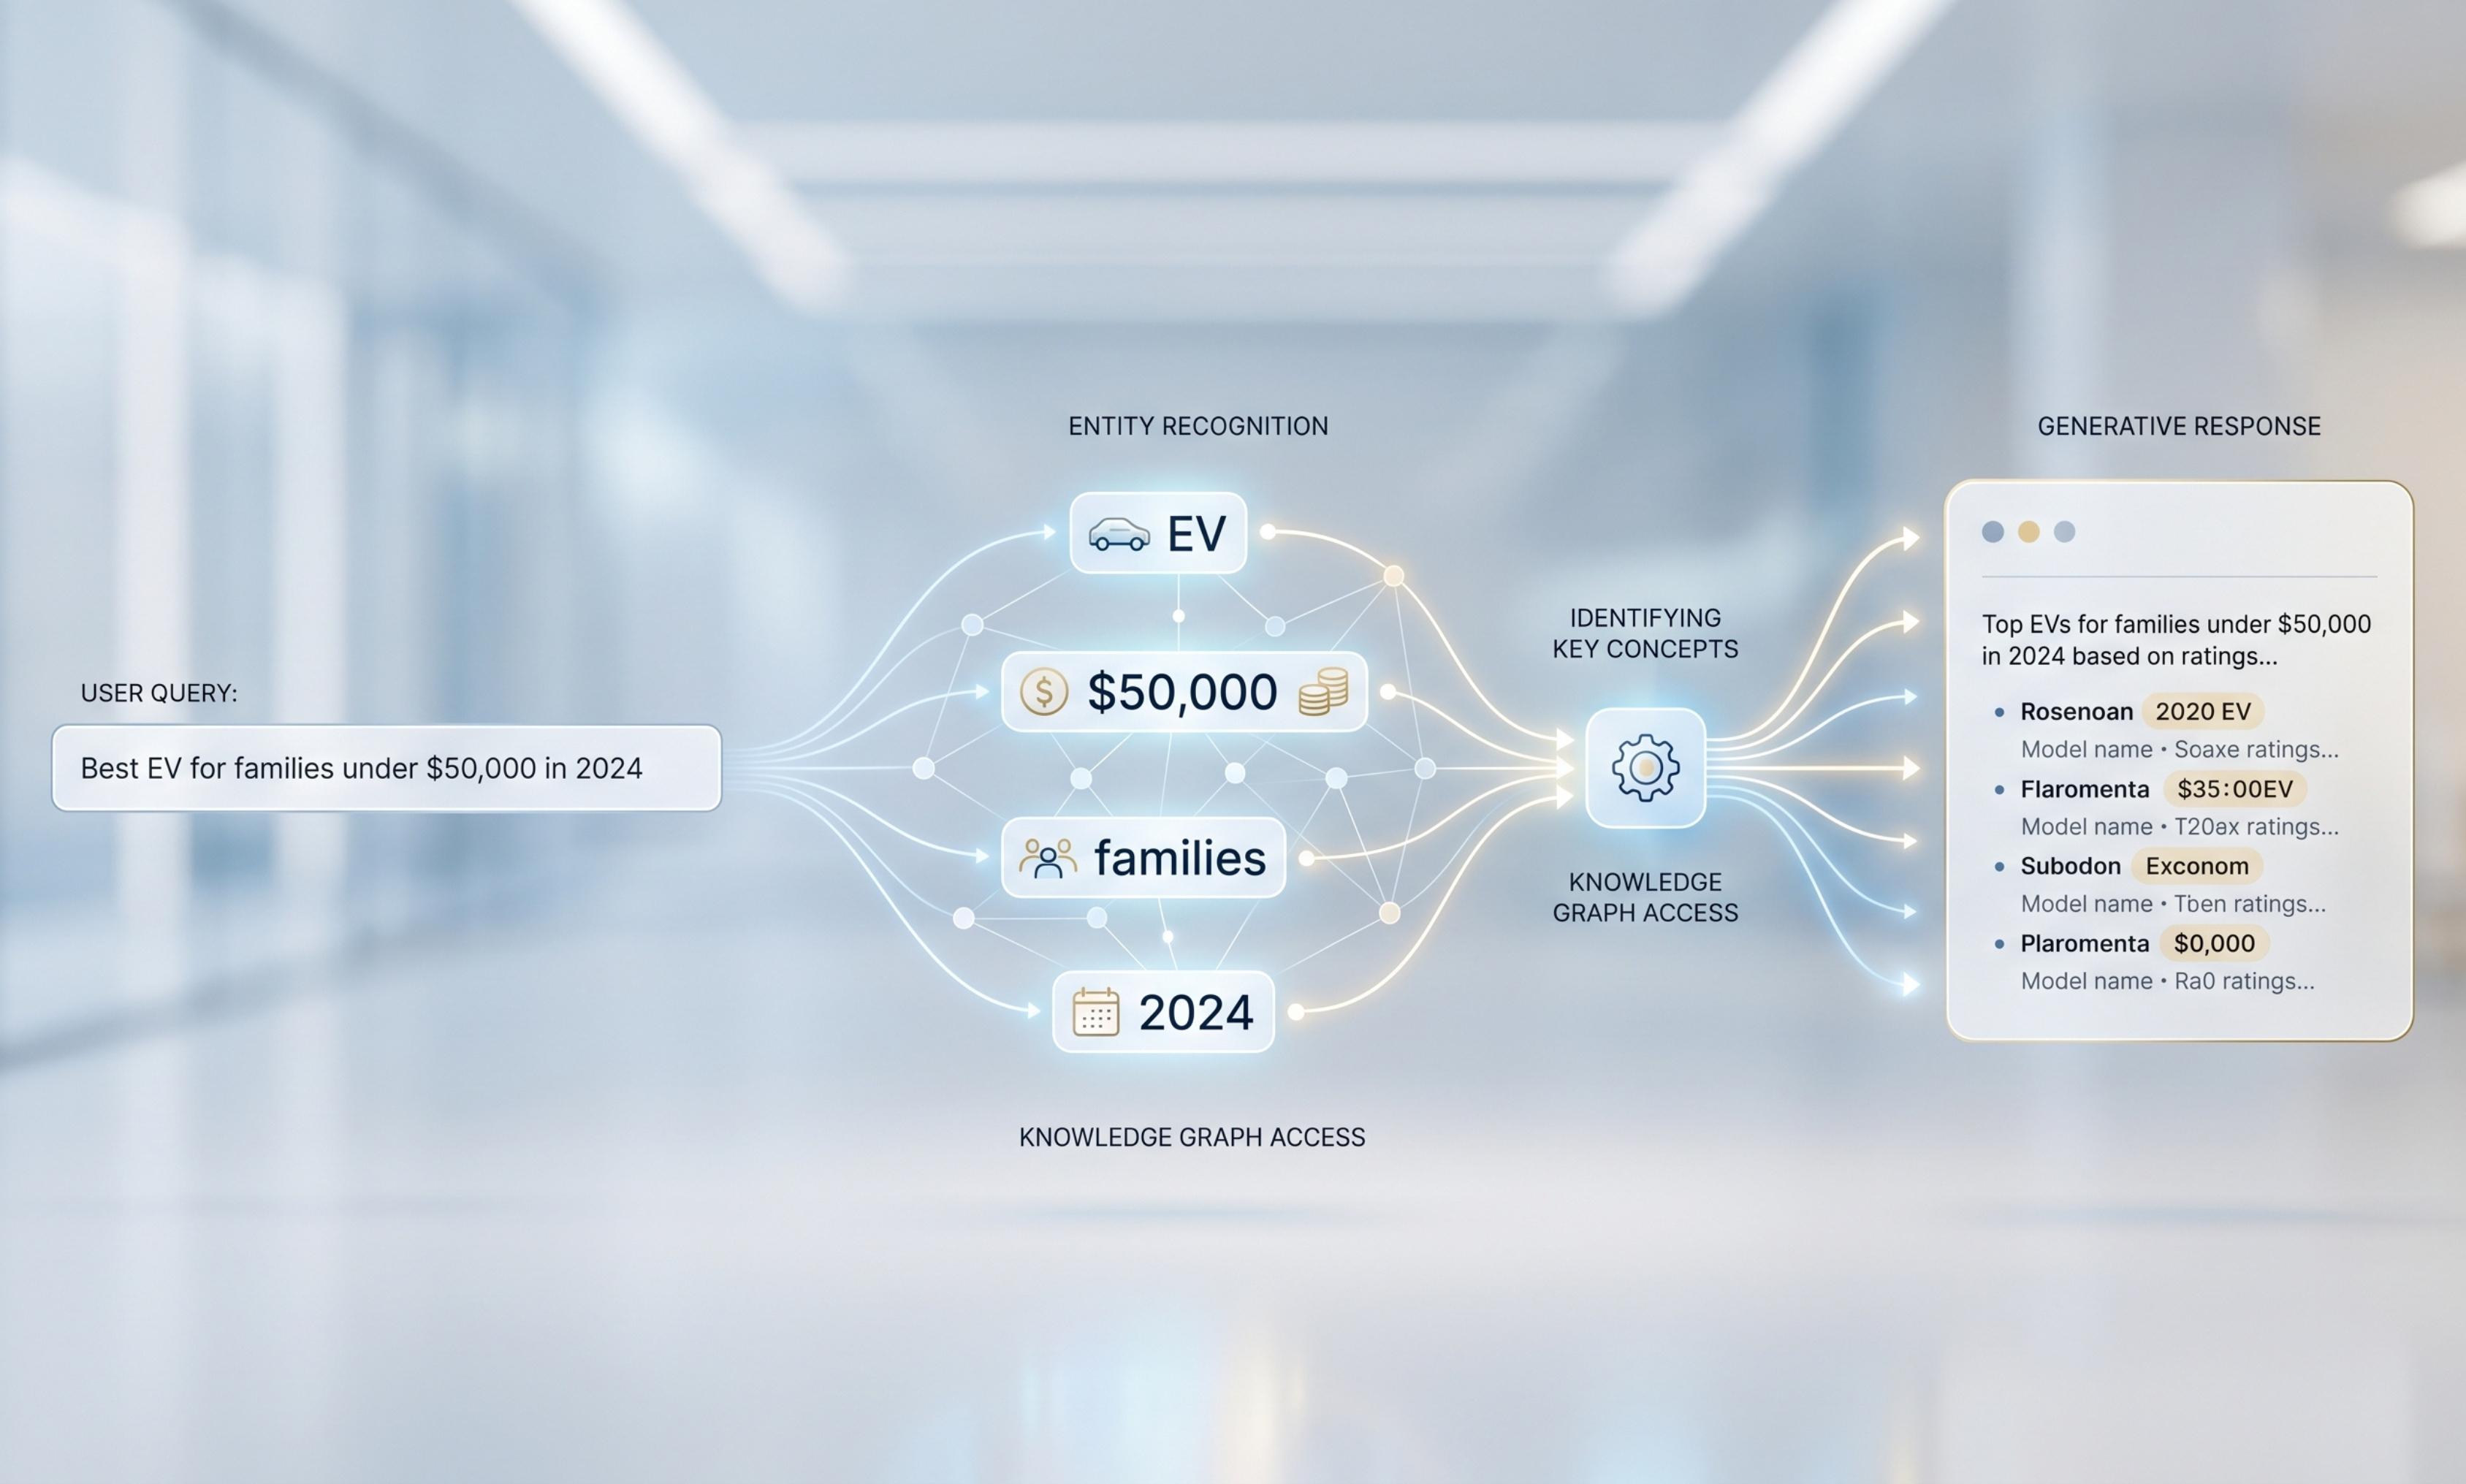
Most marketers picture AI search as “user asks question, AI gives answer.” The reality is far more elaborate. Modern AI search platforms run a multi-stage pipeline that fans out queries, retrieves passages, classifies intent, and synthesizes responses through specialized language models. Understanding this pipeline is what separates brands that engineer for AI visibility from brands that hope for it.
The Eight-Stage Pipeline
Here’s what actually happens between a user typing a query and an AI assistant returning a cited answer:
- Query intake. User submits a query. Could be text, voice, image, or multimodal. Non-text inputs are converted to machine-readable formats.
- User state retrieval. The system pulls contextual information about the user, including prior queries, location, device, active applications, and stored preferences. This becomes the “user state.”
- Query fan-out. Large language models expand the original query into dozens of synthetic sub-queries, including alternative phrasings, drill-down questions, and entity-based reformulations.
- Document retrieval. Synthetic queries trigger retrieval across multiple data sources, building a custom corpus of passages relevant to the user’s intent.
- Query classification. The combined data gets classified into response categories (“needs creative text,” “benefits from summarization,” “needs clarification”) to route to the right specialized LLM.
- Multi-stage LLM processing. Specialized downstream LLMs process the corpus, build reasoning chains, and synthesize a coherent response.
- Source citation. AI-generated text gets compared against potential source documents using semantic embeddings. Sufficiently close matches get linkified as citations.
- Personalized output. Final response is delivered, often with multimodal elements (images, tables, video), tailored to the user state.
Each step creates an opportunity for your content to be selected or skipped. Brands that engineer for the pipeline win. Brands that don’t, lose.
Where Semantic Understanding Comes In
This is the part most SEO teams miss. AI search isn’t keyword matching anymore. It’s semantic understanding through entity awareness at every stage:
| Stage | Entity Role |
|---|---|
| Query understanding | NER identifies entities in the user’s query and links them to canonical IDs |
| Personalization | User state embeddings reference entities the user cares about |
| Query fan-out | Knowledge graph relationships expand entities to broader/narrower equivalents |
| Document retrieval | Passages are retrieved based on entity matches, not keyword density |
| Reranking | Pages with clear entity clarity rank higher in the candidate corpus |
| Synthesis | LLMs ground responses in entity-rich passages they can verify |
| Citation | Sources with stable entity IDs and verifiable facts get cited preferentially |
Notice the pattern? At every stage, entities are the operating system. Your content’s job is to make those entities crystal clear, properly linked, and grounded in verifiable facts.
Query Reformulation vs. Query Decomposition
Two related but distinct techniques shape how AI systems handle complex queries.
Query reformulation rewrites a single query into multiple synthetic versions to improve retrieval. Example: “best electric SUV” might become “best EV SUV 2026,” “Tesla Model Y review,” “Volkswagen ID.4 specs,” and “EV SUV comparison.”
Query decomposition (also called query chunking) breaks a complex multi-intent query into independent sub-queries. Example: “Compare Pixel 9 camera to iPhone 16 and suggest accessories for hiking” breaks into:
- Retrieve Pixel 9 camera specs
- Retrieve iPhone 16 camera specs
- Synthesize comparison
- Retrieve hiking accessories
- Aggregate and rank
Both techniques rely on entity recognition to anchor each sub-query to specific things in the knowledge graph. Without strong entity coverage, your content fails to match the sub-queries AI systems generate, and you disappear from the response.
💡 Pro tip: AI systems retrieve at the passage level, not the page level. A single article can contribute multiple cited passages if each section is semantically complete and entity-rich. Optimize at the passage level, not just the page level.
Why Entity Recognition Decides AI Search Visibility
Your AI search visibility isn’t decided by domain authority, backlinks, or word count anymore. It’s decided by how cleanly AI systems can identify, disambiguate, and link the entities in your content.
What Entity Recognition Solves for AI Search
Entity recognition serves seven specific functions inside AI search systems:
- Stabilizes meaning in multimodal, stateful queries where context shifts mid-conversation
- Guides query fan-out by anchoring synthetic queries to specific entities
- Shapes hybrid retrieval by biasing document selection toward entity matches
- Constrains generation by limiting response content to the correct entities and attributes
- Selects citations by matching semantic embeddings between AI responses and source documents
- Enforces safety through entity-level policies (e.g., excluding harmful entities)
- Powers UX through entity cards, knowledge panels, comparison facets, and “next step” suggestions
Every one of those functions depends on AI systems recognizing your entities clearly. Miss any, and you become invisible inside the conversations your buyers are actually having.
The Entity Visibility Checklist
For AI search systems to confidently cite your brand, your content needs:
- Clearly named entities with stable identifiers (canonical names, schema @id)
- Linked entity references through sameAs to Wikidata, Wikipedia, LinkedIn, Crunchbase
- Concise, verifiable facts that AI systems can ground responses on
- Unique information gain that adds new value beyond what competitors publish
- Consistent entity coverage across pages, formats, and external sources
- Disambiguation signals when entity names could refer to multiple things (the technology company vs. the fruit)
- Entity-rich structure that allows passage-level retrieval
Brands that hit all seven get cited consistently. Brands that hit only three or four show up occasionally. Brands that hit fewer than three become functionally invisible to AI search.
The Quick GEO Manual for Entities
Here’s the abbreviated playbook every SEO team should run:
- Plan. Identify your priority entities. Record canonical IDs for each.
- Create. Use entity names exactly and naturally. Include common aliases.
- Disambiguate. Clarify which entity you’re discussing in the first paragraph of every page.
- Mark up. Add schema.org structured data with sameAs to canonical entity IDs.
- Link. Cluster internally by entity. Cite authoritative external sources.
- Asset. Use entity names in titles, H1s, alt text, and file names.
- Validate. Run an NLP API to extract entities and compare against your targets.
- Maintain. Track mentions and sentiment. Refresh pages to keep entity coverage consistent.
How to Check If Your Queries Are Grounded
Run this quick audit on your top queries:
- Pull your top queries from Google Search Console
- Run NER and entity linking against each query
- Flag the ones that resolve to canonical IDs (Wikidata, Knowledge Graph)
- Spot-check SERPs for knowledge panels, entity carousels, or AI overview chips (these signal entity grounding)
- For unlinked queries, add missing aliases, clarify your copy, and ensure schema links to the right IDs
This single audit will reveal which of your important queries AI systems can confidently ground and which ones they can’t. The unlinked queries are your immediate priority list.
This is the kind of foundational entity work our team handles inside LLM SEO engagements and GEO agency projects, so your brand becomes the recognized entity AI systems learn to trust and cite.
A Hands-On Entity Recognition Workflow
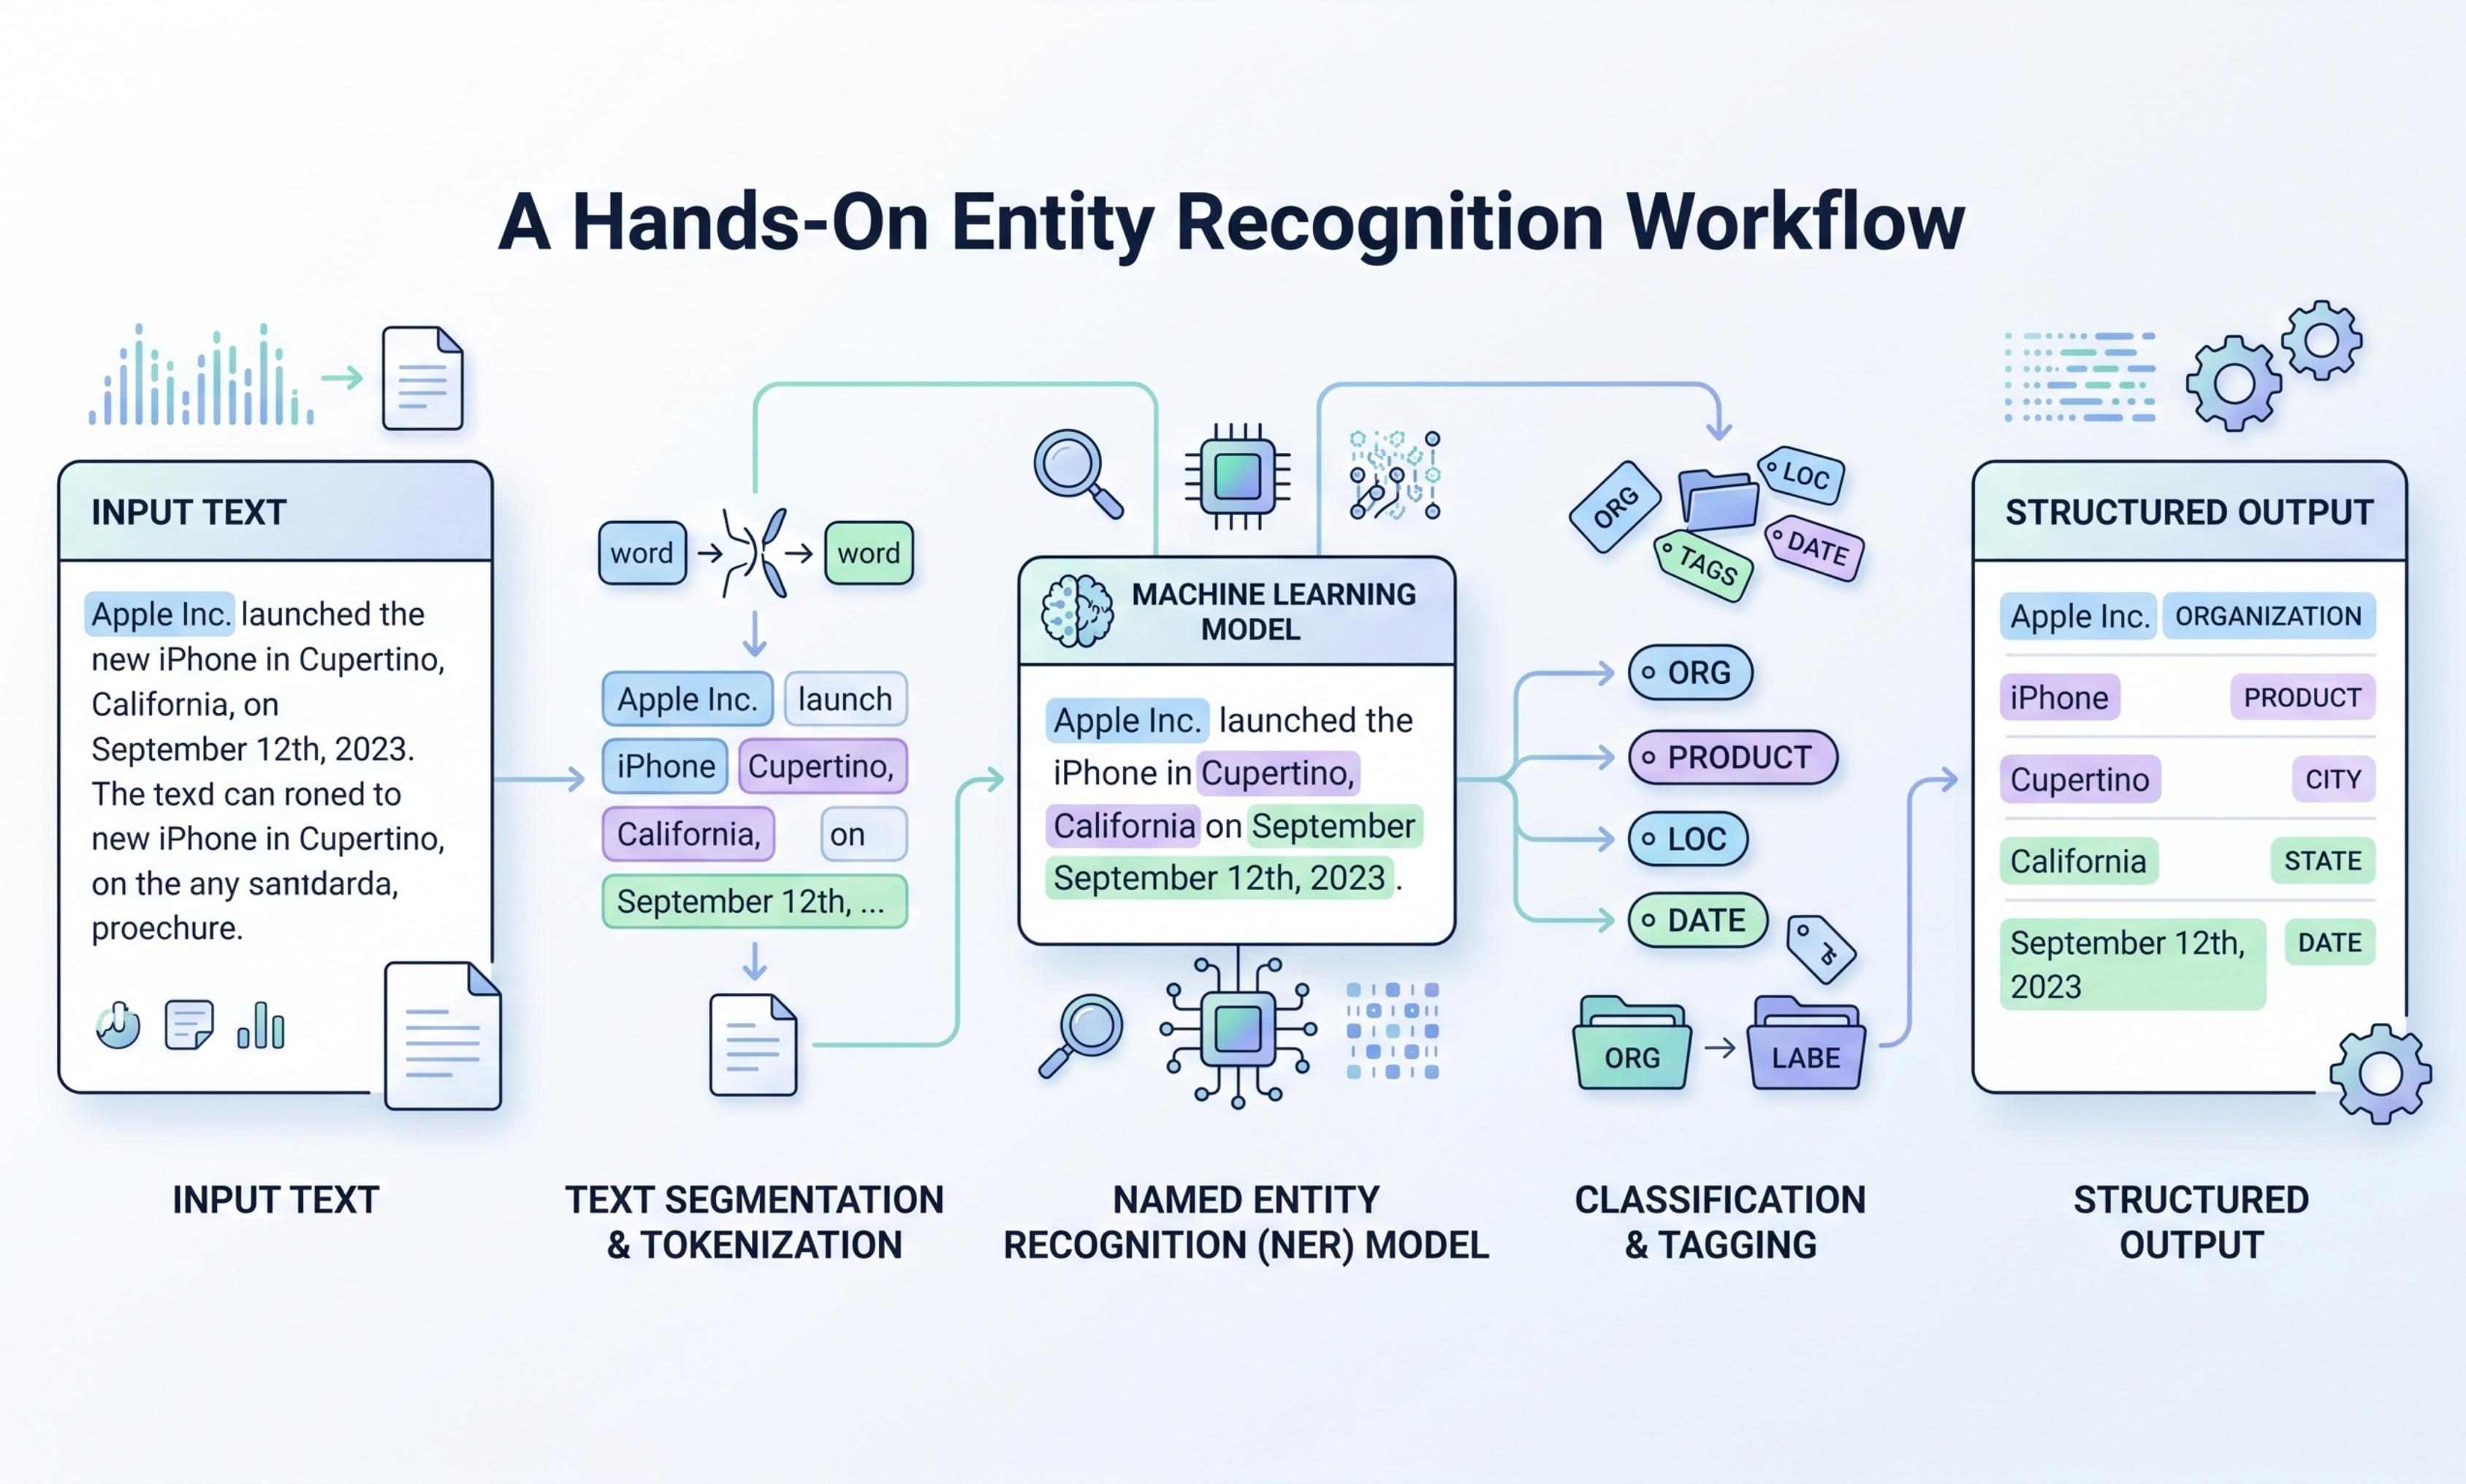
Talking about entity recognition is one thing. Actually running it on your content is another. Here’s the practical workflow we use to extract entities, link them to knowledge graphs, and feed the data back into our SEO strategy.
Step 1: Choose the Right Entity Recognition API
This is the most important decision in the workflow. Most teams default to ChatGPT or Claude for entity extraction. That’s a mistake.
Task-specific cloud NLP APIs consistently return more entities, richer metadata, and reproducible outputs than generative AI chatbots. The leaders for SEO use cases:
| API | Strengths | Best For |
|---|---|---|
| Google Cloud Natural Language | Highest entity coverage, returns Wikipedia URLs and Knowledge Graph IDs | Most SEO use cases, especially for English content |
| AWS Comprehend | Solid entity detection plus dedicated Key Phrases module | Brands needing both entities and key concepts |
| IBM Watson NLU | Relationship graphs and emotion signals | Sentiment analysis at the entity level |
| Azure Cognitive Services | Strong custom entity training | Enterprise teams with domain-specific entities |
| TextRazor | Disambiguation focus | Content with high entity ambiguity |
What to look for when evaluating:
- Coverage in your domain and target languages
- Quality (precision, recall, linking accuracy, confidence scores)
- Customization (ability to add new entities, retrain models)
- Cost, latency, and throughput
- Output format with stable IDs for cross-document tracking
For SEO workflows, Google Cloud NLP is usually the right starting point. It’s faster and cheaper than prompting a chatbot, supports free-tier trials, and returns the Knowledge Graph IDs you need for downstream work.
Step 2: Decide What Content to Extract Entities From
Don’t just analyze blog posts. Almost any text your brand or competitors produce can be mined for entities:
- Product and category pages
- Help docs and knowledge base articles
- Page titles, headings, and meta descriptions
- Long-form articles and pillar pages
- YouTube transcripts (yours and competitors’)
- Keyword lists and internal-link inventories
- Reviews and support tickets
- Blog and forum comments
- PR mentions and backlink anchor text
The goal is mapping how your brand, products, people, places, and concepts actually appear across your entire footprint. Most teams underestimate the volume of text available for analysis.
Step 3: Run a Two-Extractor Workflow
Single-API entity extraction misses entities. The fix is running two complementary extractors on the same content:
- Extractor A (Google Cloud NLP) for entity coverage with Knowledge Graph IDs
- Extractor B (AWS Comprehend) for key phrases and concepts
Reconcile the outputs to one canonical ID space (Wikidata is a sensible default). Store common aliases. Enrich with entity sentiment and mention counts to prioritize content updates.
Step 4: Extract Entities, Discover Related Entities, Explore the Knowledge Graph
Once your APIs are running, three core tasks unlock the data:
- Find entities in your content. Run entity extraction with salience, sentiment score, and magnitude per entity.
- Link entities to the Google Knowledge Graph. Capture each entity’s MID (when available), then enrich with name, description, types, official URL, image, and Wikipedia snippet.
- Discover related entities for keyword expansion. Given a seed keyword or a CSV of terms, pull the top related entities to broaden your research, content strategy, and taxonomy building.
Step 5: Use the Output to Inform Your Strategy
Raw entity extraction data is useless without action. Build these recurring workflows:
- Content gap analysis. Compare your entity coverage against top-ranking competitors. Where are they covering entities you’re missing?
- Internal linking enhancement. Use entity co-occurrence to suggest cross-links between related pages.
- Schema implementation. Use Knowledge Graph IDs to add sameAs links inside your structured data.
- Topical authority tracking. Monitor your entity coverage growth across your priority entities over time.
- Aspect-level sentiment. Track how different facets of your brand (price, support, quality) are perceived in user-generated content.
Step 6: Avoid the LLM Trap
Don’t use ChatGPT or Claude for production entity extraction. Variability is too high, structure is too weak, and outputs aren’t reproducible. Keep LLMs for content transformation tasks (summarization, title rewrites, Q&A), but route entity extraction through dedicated NER APIs.
💡 Pro tip: If your in-house team doesn’t have the bandwidth to run this workflow, our AI SEO agency builds it as part of every engagement. We extract entities, link them to canonical IDs, integrate them into schema, and report performance by entity, not just URL.
The Relevance Engineering Playbook
Building entity-aware content is the operational reality of relevance engineering. The discipline is straightforward but rarely executed well. Here’s the complete playbook our team applies inside every engagement.
Content Strategy
The first principle: AI systems retrieve and reason at the passage level, not the page level. Your content needs to be semantically complete at the chunk level.
Practical patterns that win:
- Open every section with the canonical entity name and a verifiable fact about it
- Reiterate entity attributes when you discuss core entities throughout the page
- Use multiple content formats (tables, lists, comparisons) within long-form pieces
- Make atomic assertions that can stand alone if extracted as a passage
- Be specific about products, comparisons, and trade-offs (avoid vague claims)
- Name your sources explicitly when stating facts
The goal is content where every paragraph could be lifted out as a citation and still make sense. That’s what AI systems are looking for when they assemble grounded responses.
Technical and Structured Data
Schema markup tells AI systems exactly what your entities are. The minimum implementation:
- Organization, Product, Service schema with persistent @id values
- sameAs properties linking to Wikidata, Wikipedia, LinkedIn, Crunchbase
- FAQPage schema for question-based content
- Person schema for authors and team members with verifiable profiles
- Semantic HTML with proper heading hierarchy, <article>, <section>, <time>, and <data> elements
Treat schema as infrastructure, not decoration. Run validation checks on every release. Block publishing if the critical schema fails. The brands with the cleanest entity markup get cited disproportionately because AI systems can confidently parse their content.
Entity Hubs and Internal Linking
Build hub-and-spoke clusters around each priority entity:
- One hub page per priority entity that defines it, lists attributes, and routes to related content
- 5 to 15 spoke pages per hub covering common reasoning steps (comparisons, troubleshooting, buyer’s guides)
- Intentional internal linking with anchor text that uses canonical entity names
- Cannibalization prevention by quickly merging pages competing for the same entity
Two simple rules keep clusters healthy. Link with intent. Merge fast, duplicate slow.
Multimodal Consistency
AI search platforms summarize across formats. Keep your entity story consistent everywhere:
- Transcripts should name the same entities your articles reference
- Captions should serve as short, structured summaries with the right entity labels
- Image alt text should align with hub @id values
- Video titles, descriptions, and chapter markers should reinforce primary entities
- Social profiles should use identical brand and product names
YouTube is the third most-cited source by LLMs. Brands that maintain consistent entity labels across video, audio, and text earn an outsized citation share.
Mindset and Team Operations
The unglamorous foundation of every strong entity strategy is a spreadsheet. List the things you care about (brands, models, categories, people, locations) and give each a permanent canonical ID. Never recycle IDs.
Aim for canonical entity governance with these elements:
- Permanent @id values for every entity in your model
- Owner assignment by entity cluster (Editorial, SEO, Engineering)
- Merge and split rules for when variants become their own entities
- Changelog tracking of renames, merges, and entity evolution
- Multi-language consistency (one ID per thing across all locales)
This governance layer is what prevents entity drift over time. Without it, your entity model fragments within 12 to 18 months as teams rotate, services change, and copy shifts.
Relevance Engineering and Measurement
You can’t engineer relevance you can’t measure. Track entity-level performance with these core metrics:
| Metric | What It Tells You | Cadence |
|---|---|---|
| Entity coverage | % of priority entities with a credible hub plus 3+ supporting pieces | Weekly |
| Schema validity | CI pass rate for JSON-LD; ID conflicts (target: zero) | Per release |
| Performance by entity | Impressions, CTR, conversions grouped by entity (not URL) | Weekly |
| Ambiguity rate | % of entity mentions with 2+ plausible matches | Weekly |
| Agility | Time from emerging entity detection to live hub | Monthly |
Build dashboards by entity, not just URL. The brands winning AI search visibility report performance the way AI systems actually evaluate content: by the things, not the pages.
Entity Governance
Strong governance prevents entity drift and keeps your authority concentrated. Set up alerts for:
- Unknown entities appearing in your search logs
- Unusual spikes on known entities
- Schema regressions that should block a release
In your CMS, build a sidebar that surfaces the canonical entity for each article, suggests internal links to the hub and nearest spokes, and provides a ready-to-paste JSON-LD stub with the correct @id. On-site search should respect the same canonical entity model, with filters powered by your alias dictionary.
Weekly maintenance stays boring on purpose. Sync aliases. Verify sameAs links resolve. Rerun schema tests in CI. Log merges and splits in your entity changelog.
💡 Pro tip: The brands quietly dominating AI search aren’t writing more content. They’re publishing entity-grounded passages, governing their canonical entity model, and measuring everything at the entity level. That’s relevance engineering in practice.
This complete playbook is what our team builds for clients across every LLM SEO engagement, structured data implementation, and GEO agency project we ship. Entity recognition isn’t a feature we add. It’s the operating system we build everything else on top of.
The brands that engineer for entities now will own AI search visibility for the next decade. The ones still chasing keywords will spend that decade wondering why their competitors keep showing up in every AI conversation in the category.
What Entity Recognition Actually Costs to Run
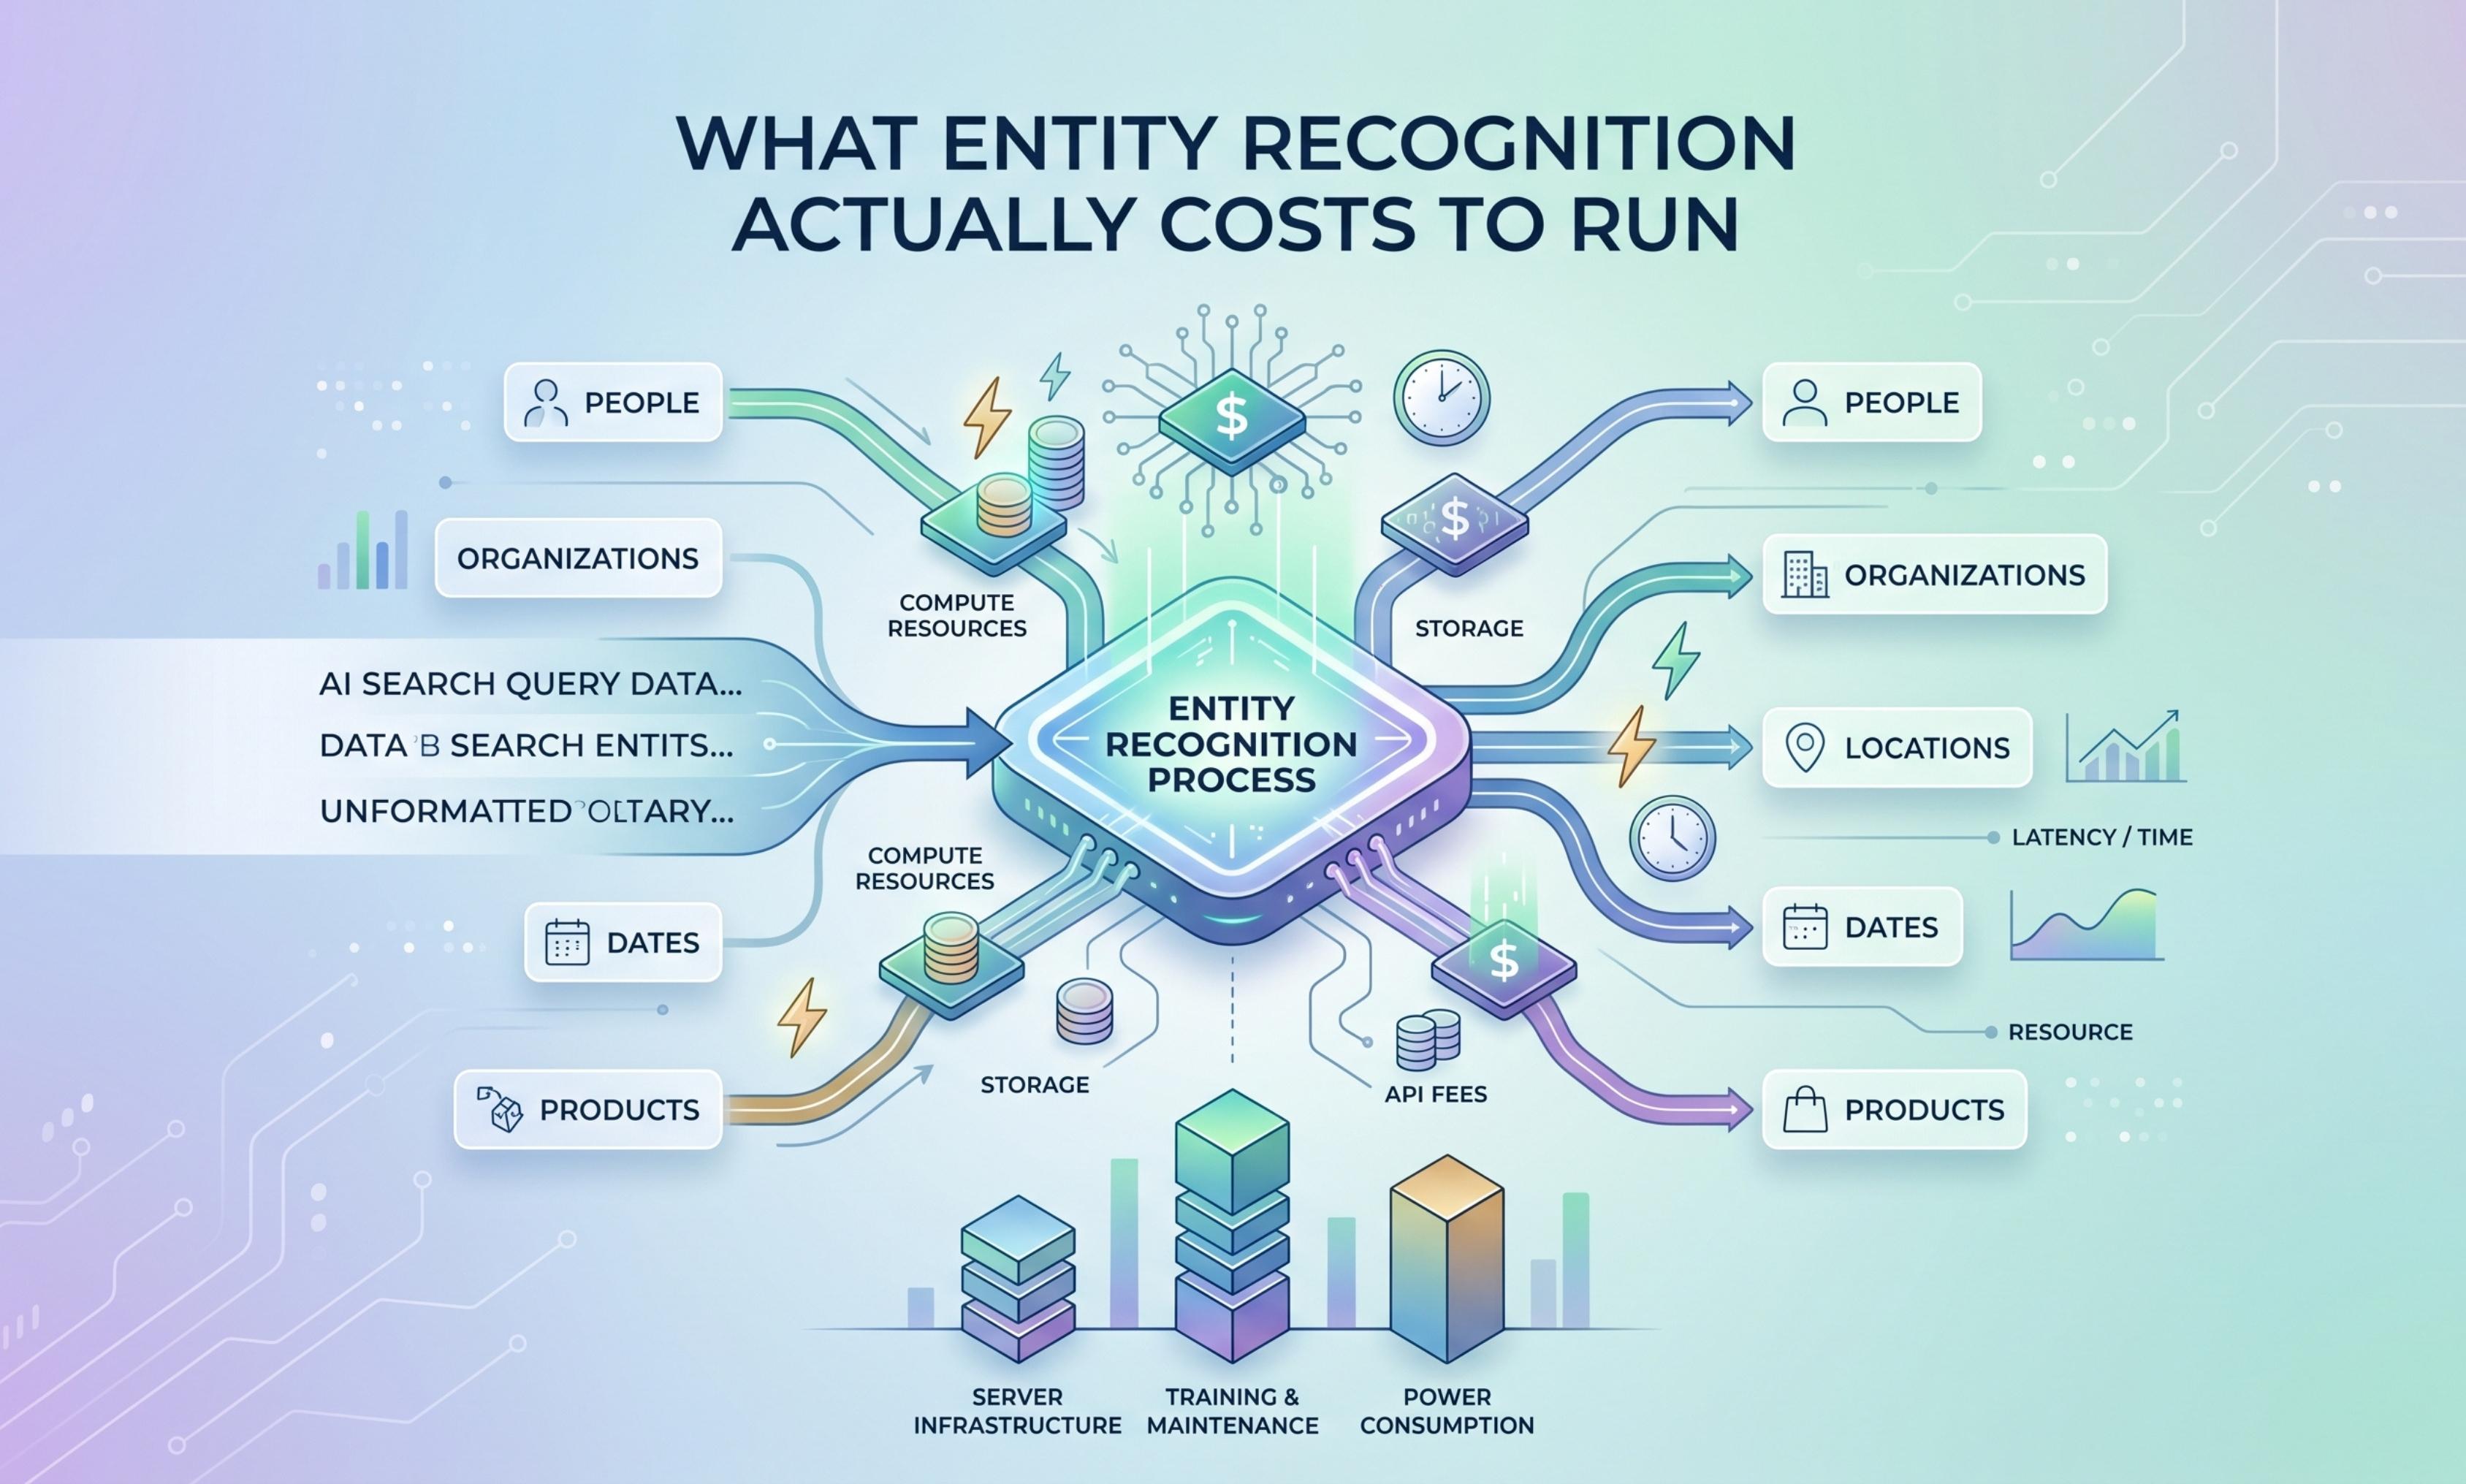
Here’s what to budget for.
The Hidden Operational Layer
Running entity recognition properly requires real operational investment beyond the API subscription. The work breaks down into four areas:
| Operational Area | What It Actually Involves |
|---|---|
| Data preparation | Cleaning, formatting, and chunking content before extraction. The single biggest time sink most teams underestimate |
| Computational resources | API calls, storage for entity tables, embedding generation, and reconciliation jobs |
| Governance and review | Maintaining canonical ID tables, alias dictionaries, and reviewing edge cases |
| Integration | Connecting entity data to your CMS, schema generator, internal linking tools, and reporting layer |
The API itself is rarely the bottleneck. The work that surrounds it is what separates teams that successfully run entity programs from teams that abandon them after three months.
What “At Scale” Actually Means
For a small to mid-sized site (under 500 pages), entity recognition is achievable on a few hundred dollars a month plus 10 to 15 hours of weekly maintenance. You can extract entities, link them to canonical IDs, build entity associations, and report performance without significant overhead.
For enterprise sites with thousands of pages, multiple languages, and dozens of priority entities, the equation shifts. You’re now looking at:
- API costs scaling with content volume and reanalysis frequency
- Engineering time for pipeline automation
- Dedicated entity governance roles
- Custom dashboards integrating entity data with traditional SEO metrics
The good news: the ROI compounds. Once your canonical entity model exists, every piece of new content you create slots into it cleanly. Entity chunking improves automatically. Schema generation becomes templated. Internal linking suggestions write themselves.
What to Prioritize When You Can’t Do Everything
If you’re starting from zero, this is the order that delivers the most search relevance per hour invested:
- Define your top 10 priority entities. These are the things your brand absolutely needs AI systems to recognize. Skip the long tail for now.
- Run entity extraction on your top 20 pages. Identify gaps where key entities are mentioned but unlinked, or where understanding entities depends on context that the page doesn’t provide.
- Add schema markup with stable @id values to those top 20 pages first. This single move transforms how AI systems handle multiple queries about your brand.
- Build the canonical entity table. One row per entity, with name, ID, aliases, sameAs links, and ownership.
- Layer in measurement. Track how often your brand appears in AI responses for priority queries, then expand from there.
This 80/20 approach ignores the long tail of relevant entities until your foundation is solid. It plays a crucial role in keeping the work manageable while still delivering visible AI visibility wins within 90 days.
The Trap to Avoid
Don’t try to extract entities from every page on your site in week one. Teams that do this drown in data, lose focus, and end up with no actionable insights. Start narrow, build the canonical model, prove the value on priority entities, then expand outward.
Building entity authority is a discipline of compounding focus, not breadth. The brands that nail their top 10 entities consistently outperform brands that spread thin across 200.
💡 Pro tip: If your team doesn’t have the bandwidth to run this operational layer, that’s exactly where an experienced AI SEO partner earns their fee. Done right, the operational discipline pays back its cost within 6 to 9 months in compounding citations and AI visibility.
This is the practical reality of building entity authority at scale, and it’s the layer most agencies either skip or overcomplicate. We’ve designed our entity workflows specifically to right-size for each client’s stage and resources, so the discipline becomes sustainable instead of becoming yet another project that stalls in month four.
Win AI Search Recognition With Doc Digital SEM
Entity recognition is the operating system of AI search. Brands that engineer for entities (clear definitions, stable IDs, knowledge graph alignment, passage-level structure) win citations across every AI platform. The ones still chasing keyword density quietly disappear.
Here’s what to remember:
- AI search retrieves and reasons at the passage level, not the page level
- NER identifies entities, and entity linking maps them to canonical IDs
- Knowledge graphs are the trust layer that AI systems use to verify your brand
- Schema markup, sameAs links, and stable @id values are non-negotiable
- Measure performance by entity, not URL
The brands engineering entity recognition now will own AI search visibility for the next decade. Doc Digital SEM builds that foundation end to end. Get your free AI visibility audit (valued at $1,500) or explore our LLM SEO services and start owning the entities that matter.
FAQs
What is entity recognition in AI search?
Entity recognition is the artificial intelligence process of identifying and classifying potential entities in text into predefined categories like person, organization, or geographic location.
How does NER work?
NER uses training data, part-of-speech tags, and machine learning to classify entities, recognizing named entities and extracting relevant information from unstructured text.
Why is entity recognition important for SEO?
Entity SEO helps search engines understand your brand, build entity authority, and surface relevant search results across AI systems and traditional search.
What’s the difference between NER and entity linking?
NER handles entity identification and entity classification. Entity linking maps entities extracted to canonical knowledge graph IDs, resolving multiple meanings of the same word.
Can I use ChatGPT for entity recognition?
No. Use task-specific NLP APIs for production entity understanding. LLMs are unreliable, computationally expensive, and weak on error analysis, especially in specialized domains like legal research.


