


Most websites are a pile of pages held together by a navigation menu. AI search systems can’t reason about that. They need structure: clear entities, defined relationships, and machine-readable facts they can pull into AI generated answers. Without that structure, your brand stays invisible, no matter how much content you ship.
Industry analysts now agree that GraphRAG, the technique combining LLMs with knowledge graphs, has become the reference architecture for production AI systems in 2026. The brands earning consistent citations across ChatGPT, Gemini, Claude, and Perplexity have one thing in common: their websites are structured like knowledge graphs.
Here’s what we’ll talk about:
- What turning your website into a knowledge graph actually means (the SEO version)
- Step 1: Extract entities from your site using LLMs
- Step 2: Map relationships between services, locations, products, and content
- Step 3: Structure your data with schema markup and JSON-LD
- How this aligns with Google’s Knowledge Graph and earns AI citations
This is exactly the workflow our team ships for clients across SaaS, healthcare, and B2B services. Doc Digital SEM transforms websites into machine-readable knowledge graphs through our LLM SEO services and structured data implementation, so your brand becomes the recognized entity that AI systems learn to cite, not just another page they scroll past.
What Turning Your Website Into a Knowledge Graph Actually Means
Forget the engineering jargon for a second. When we say “turn your website into a knowledge graph using LLMs,” we’re not asking you to spin up a Neo4j database or write Cypher queries. We’re talking about restructuring your site’s content, schema, and relationships so AI systems can read it the same way they read traditional knowledge graphs. Same outcome, different execution.
The Two Definitions to Know
There’s a developer version and an SEO version of this concept. They’re related but different.
| Version | What It Means | Who Builds It |
|---|---|---|
| Developer version | Building a literal graph database (Neo4j, TigerGraph) from your unstructured data, with explicit nodes and edges | Engineering teams running internal AI tools |
| SEO version | Structuring your website’s pages, content, and schema so AI systems can interpret it as if it were a knowledge graph | Marketing and SEO teams chasing AI visibility |
The SEO version is what 95% of brands actually need. You don’t need a separate database. You need your website to behave like one when AI tools crawl, parse, and cite it.
What Your Site Looks Like as a Knowledge Graph
When done right, your website becomes a structured representation of:
- Entities (your brand, services, products, locations, leadership)
- Relationships (which service is offered where, which product belongs to which category, which page covers which topic)
- Attributes (founding date, pricing approach, geographic coverage, certifications)
- External references (sameAs links to Wikidata, Wikipedia, Crunchbase, LinkedIn)
When AI tools crawl your site, they extract this structured representation directly from your schema markup, content hierarchy, and internal linking. Instead of scraping raw text and guessing what your site is about, they see a clean, navigable knowledge model.
Why This Matters Right Now
Modern AI systems use retrieval augmented generation (RAG) to ground their answers in trusted sources. AI tools prefer knowledge graphs over raw text data because graphs reduce hallucinations, support multi-hop reasoning, and deliver more relevant responses than vector search alone.
The brands whose websites read like knowledge graphs to AI tools win the citation lottery. The ones that don’t get filtered out before the AI even considers them.
This is exactly why our LLM SEO services and structured data implementation work focus on graph-aligned site structure, not just content production. The structure is the leverage.
Step 1: Extract Entities From Your Site Using LLMs
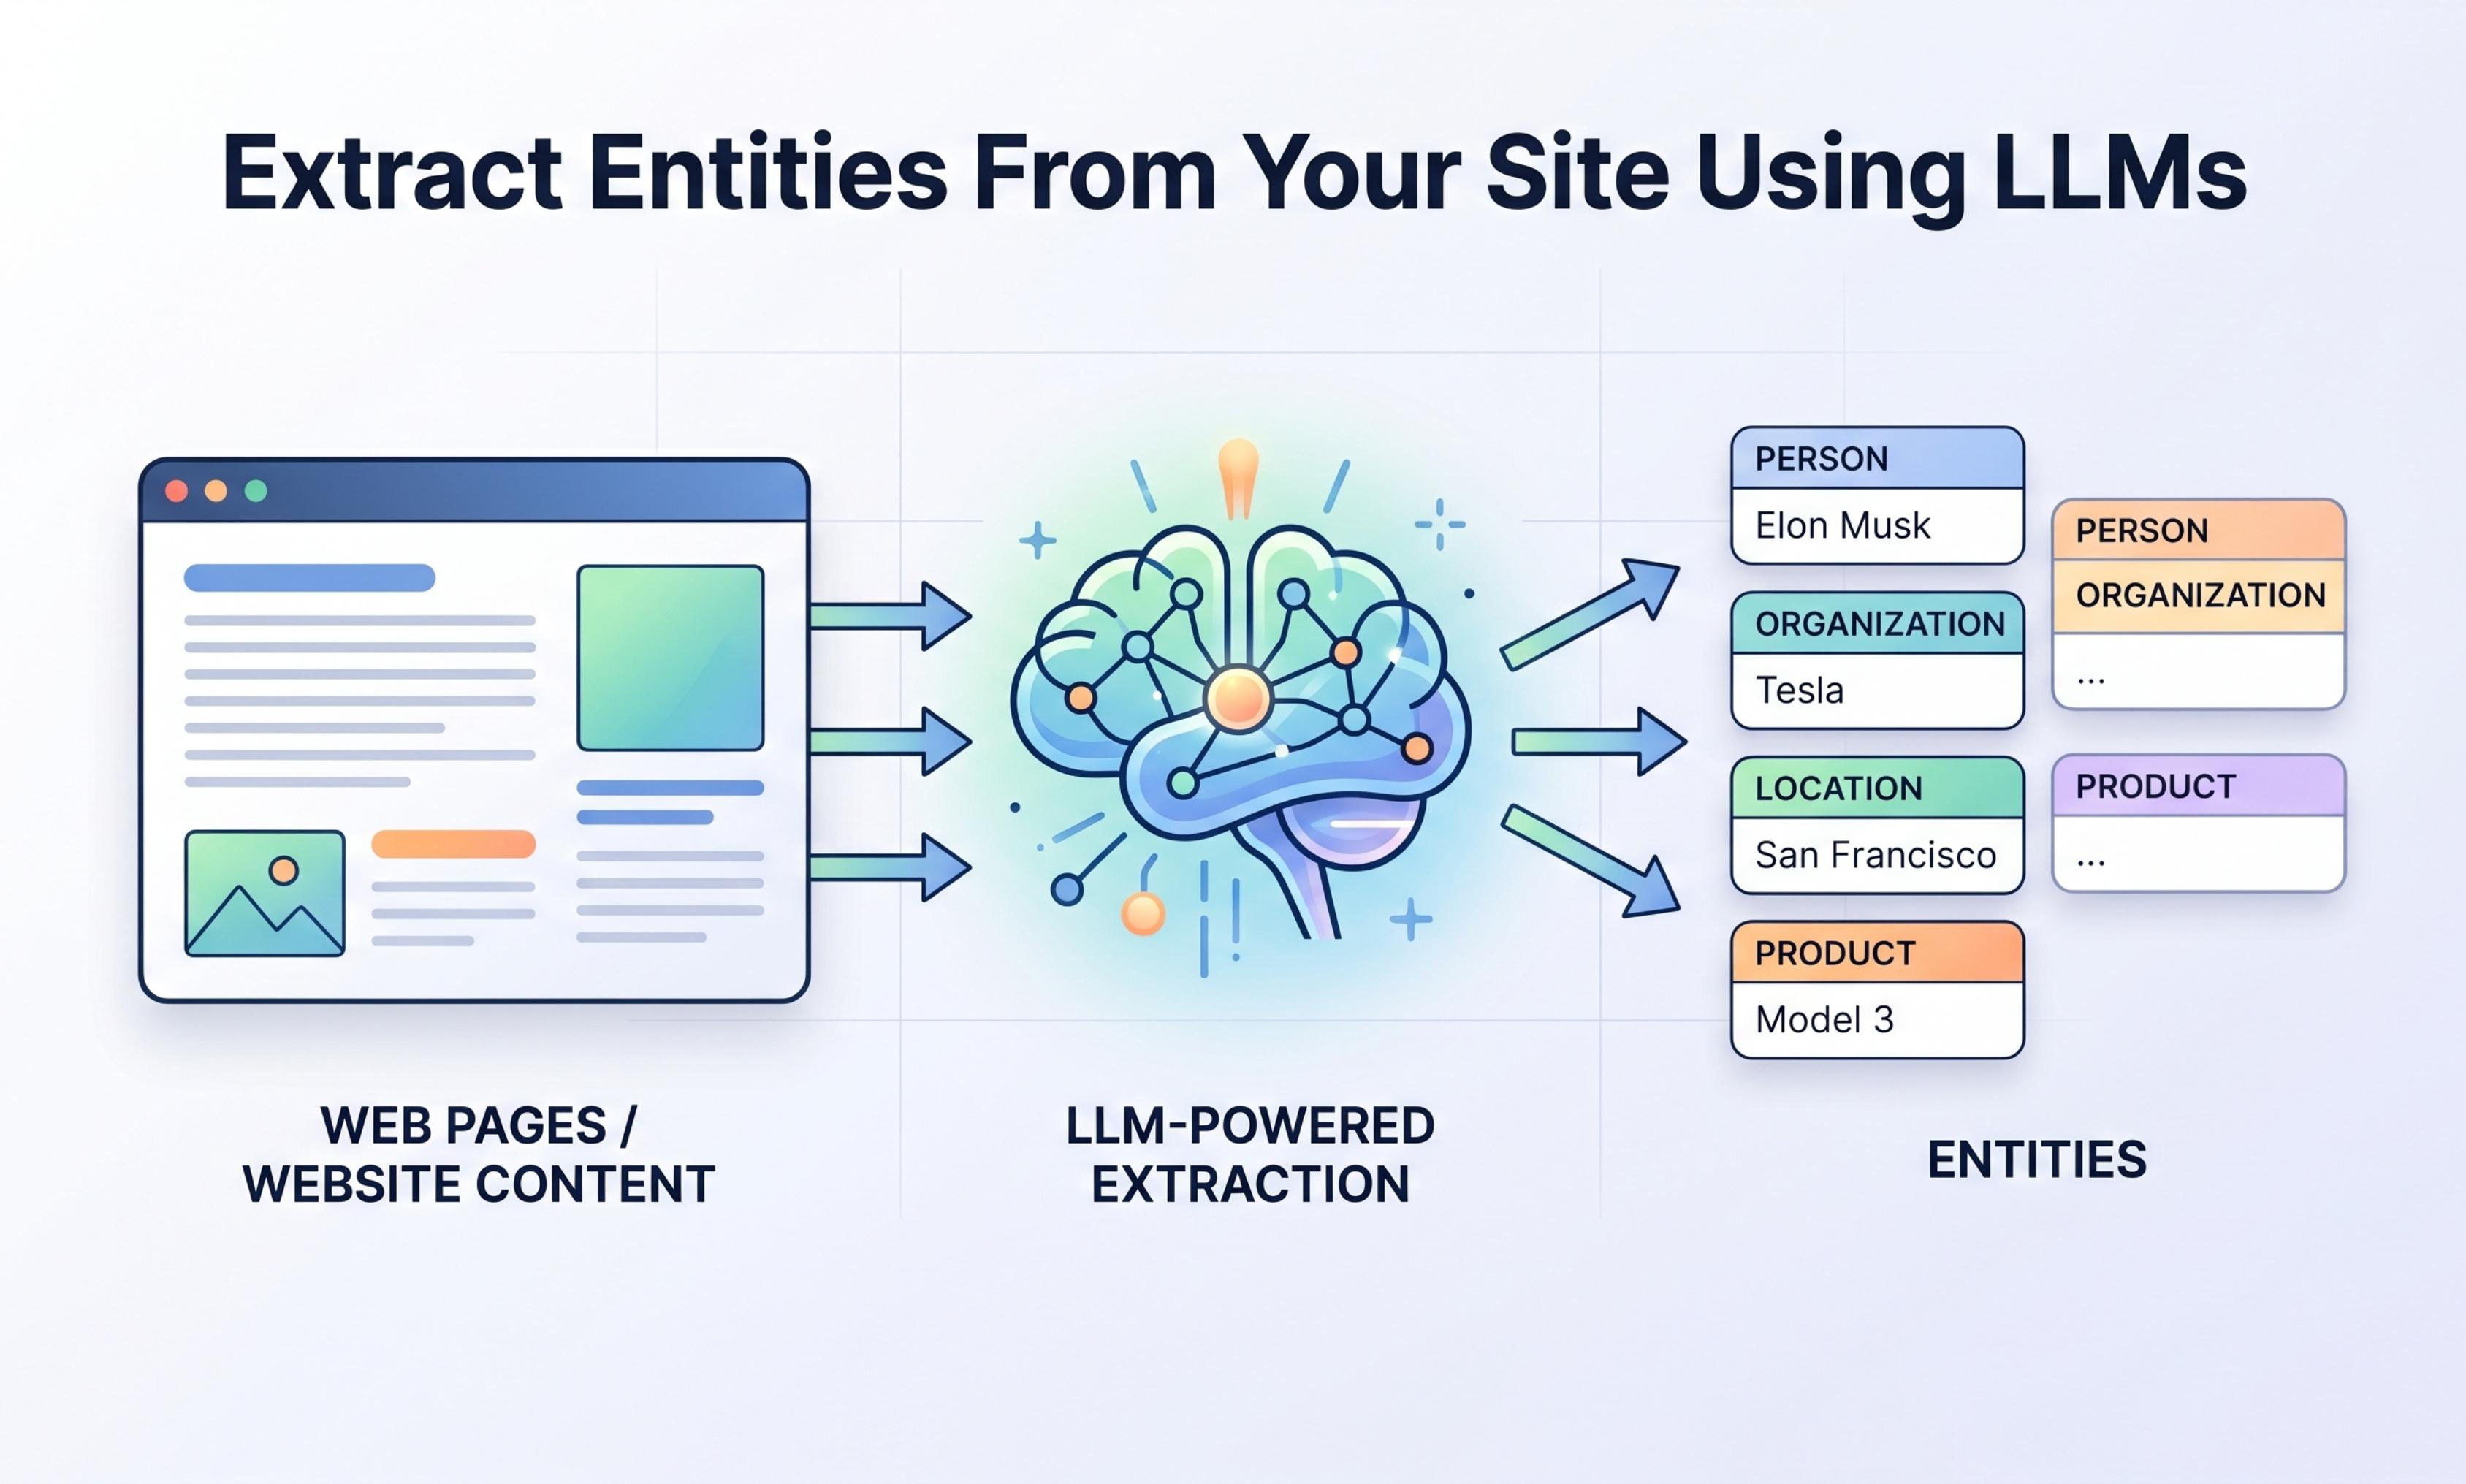
Before you can structure anything, you need to know which entities actually exist across your website. Most teams skip this step and dive straight into schema markup, then wonder why their AI visibility doesn’t move. The fix is running entity extraction first, then building everything else on top of the data.
Pick the Right Tool for the Job
You have three realistic options for extracting entities from your site:
| Tool | Best For | Considerations |
|---|---|---|
| Google Cloud Natural Language API | Production-grade entity extraction with Knowledge Graph IDs | Returns the cleanest data; sub-cent per call |
| AWS Comprehend | Entity + key phrases combined | Strong fallback; pairs well with Google Cloud NLP |
| LangChain LLMGraphTransformer | Building deeper graph structures with relationship inference | Requires an OpenAI API key; more flexible but resource-intensive |
For most marketing and SEO teams, Google Cloud NLP is the right starting point. It returns entity types, salience scores, sentiment, and (crucially) Wikipedia URLs and Knowledge Graph IDs. Those IDs become the connective tissue of your graph in step three.
If you want to use open source tools, the LangChain LLMGraphTransformer plus a local Ollama LLM gets you there too, just with more configuration.
What Content to Extract Entities From
Don’t just analyze your homepage. Run entity extraction across:
- All service and product pages
- Location pages (especially for local SEO)
- Top blog posts and pillar content
- About, leadership, and team pages
- Case studies and customer-facing PDF documents
- Any internal documents or knowledge base articles you publish externally
- Site titles, headings, and meta descriptions
The goal is mapping how your brand’s key entities appear across your entire digital footprint. Most teams underestimate the volume of entity data sitting in their existing content.
A Simple Workflow
For a typical site with 50 to 500 pages, here’s the realistic workflow:
- Crawl your site with a tool like Screaming Frog, Sitebulb, or Crawl4AI to extract clean text from every page
- Pipe the text into Google Cloud NLP (or your chosen API) for entity recognition and entity extraction
- Capture the output: entity name, type (Person, Organization, Product, Location), salience score, Wikipedia URL, Knowledge Graph MID
- Standardize entity names (handle “NYC” vs. “New York” vs. “New York City” as the same canonical entity)
- Build a master entity list in a spreadsheet or simple data model
After this step, you’ll have a structured representation of every entity your site mentions and how often each one appears. That’s the raw data you’ll use for everything that follows.
💡 Pro tip: When you extract entities, prioritize the ones with high salience scores and matching Knowledge Graph IDs. These are the entities AI systems already recognize, which means they’ll be the easiest to reinforce through schema and content.
For a deeper read on entity extraction mechanics, our breakdown on how AI search platforms leverage entity recognition covers the technical details most teams skip.
Step 2: Map Relationships Between Your Entities
Entity extraction gives you the nodes. Relationship mapping gives you the edges. Without edges, your knowledge graph is just a list of disconnected points.
What Relationships to Map
For most websites, four relationship types matter most:
| Relationship | Example |
|---|---|
| Brand → Services | “Doc Digital SEM” → offers → “LLM SEO” |
| Brand → Locations | “Doc Digital SEM” → operates in → “Fort Lauderdale” |
| Service → Industries | “LLM SEO” → serves → “B2B SaaS” |
| Service → Sub-services | “LLM SEO” → includes → “ChatGPT SEO” |
| Brand → People | “Doc Digital SEM” → founded by → “Abner [Last Name]” |
| Content → Topics | “Blog post X” → covers → “Entity-based architecture” |
| Product → Attributes | “AP-200 Air Purifier” → has feature → “HEPA-13 filter” |
The structured graph data you create here is what AI systems use to reason across multiple entities when answering complex questions. Without these relationships, your site is a flat collection of pages. With them, it becomes a navigable graph that AI tools can traverse.
How to Map Relationships at Scale
You have two ways to do this. The manual way works for small sites. The LLM-assisted way scales for everything else.
The Manual Method
Build a simple spreadsheet with three columns: subject, predicate, and object. For example:
- Doc Digital SEM | offers | LLM SEO
- Doc Digital SEM | offers | GEO
- Doc Digital SEM | operates in | Fort Lauderdale
- LLM SEO | serves | B2B SaaS
- LLM SEO | includes | ChatGPT SEO
This is essentially a list of semantic triples (subject-predicate-object), the same format used in RDF data and the semantic web. For sites with under 50 pages, manual mapping is the cleanest approach.
The LLM-Assisted Method
For larger sites, use an LLM to extract subject-predicate-object triples directly from your content. Tools like LangChain’s LLMGraphTransformer, Neo4j’s LLM Graph Builder, or a custom pipeline using OpenAI’s API can identify relationships across thousands of pages in hours instead of weeks.
A typical prompt template for relationship extraction:
“Extract all subject-predicate-object triples from the following text. Return as JSON with keys ‘head’ (subject), ‘relation’ (predicate), and ‘tail’ (object). Use canonical entity names. Avoid pronouns.”
The LLM reads each chunk of your text data and returns structured triples that you then load into your data model. This is the same approach used in production GraphRAG systems, just applied to your website content.
Don’t Forget Internal Linking
Relationship mapping isn’t just about what’s in your data model. It’s also about how your site’s pages link to each other. Internal links are the visible relationships AI tools can crawl directly.
The pattern that works:
- Hub pages link down to all related cluster pages
- Cluster pages link back up to their hub using canonical entity names
- Related clusters link laterally to each other
- Anchor text uses entity names, not “click here”
- Topic relationships get reinforced through consistent anchor patterns
When your internal linking matches your data model, AI systems can confirm the relationships in your schema by traversing the structure of your site. That redundancy is what makes the graph trustworthy.
📊 Worth knowing: Pages with strong internal linking + matching schema relationships get cited 3 to 5x more often than pages with strong content alone. The relationship layer is the leverage.
For deeper guidance, our breakdown on entity-based architecture in SEO walks through the relationship mapping discipline at depth.
Step 3: Structure Your Data With Schema Markup and JSON-LD
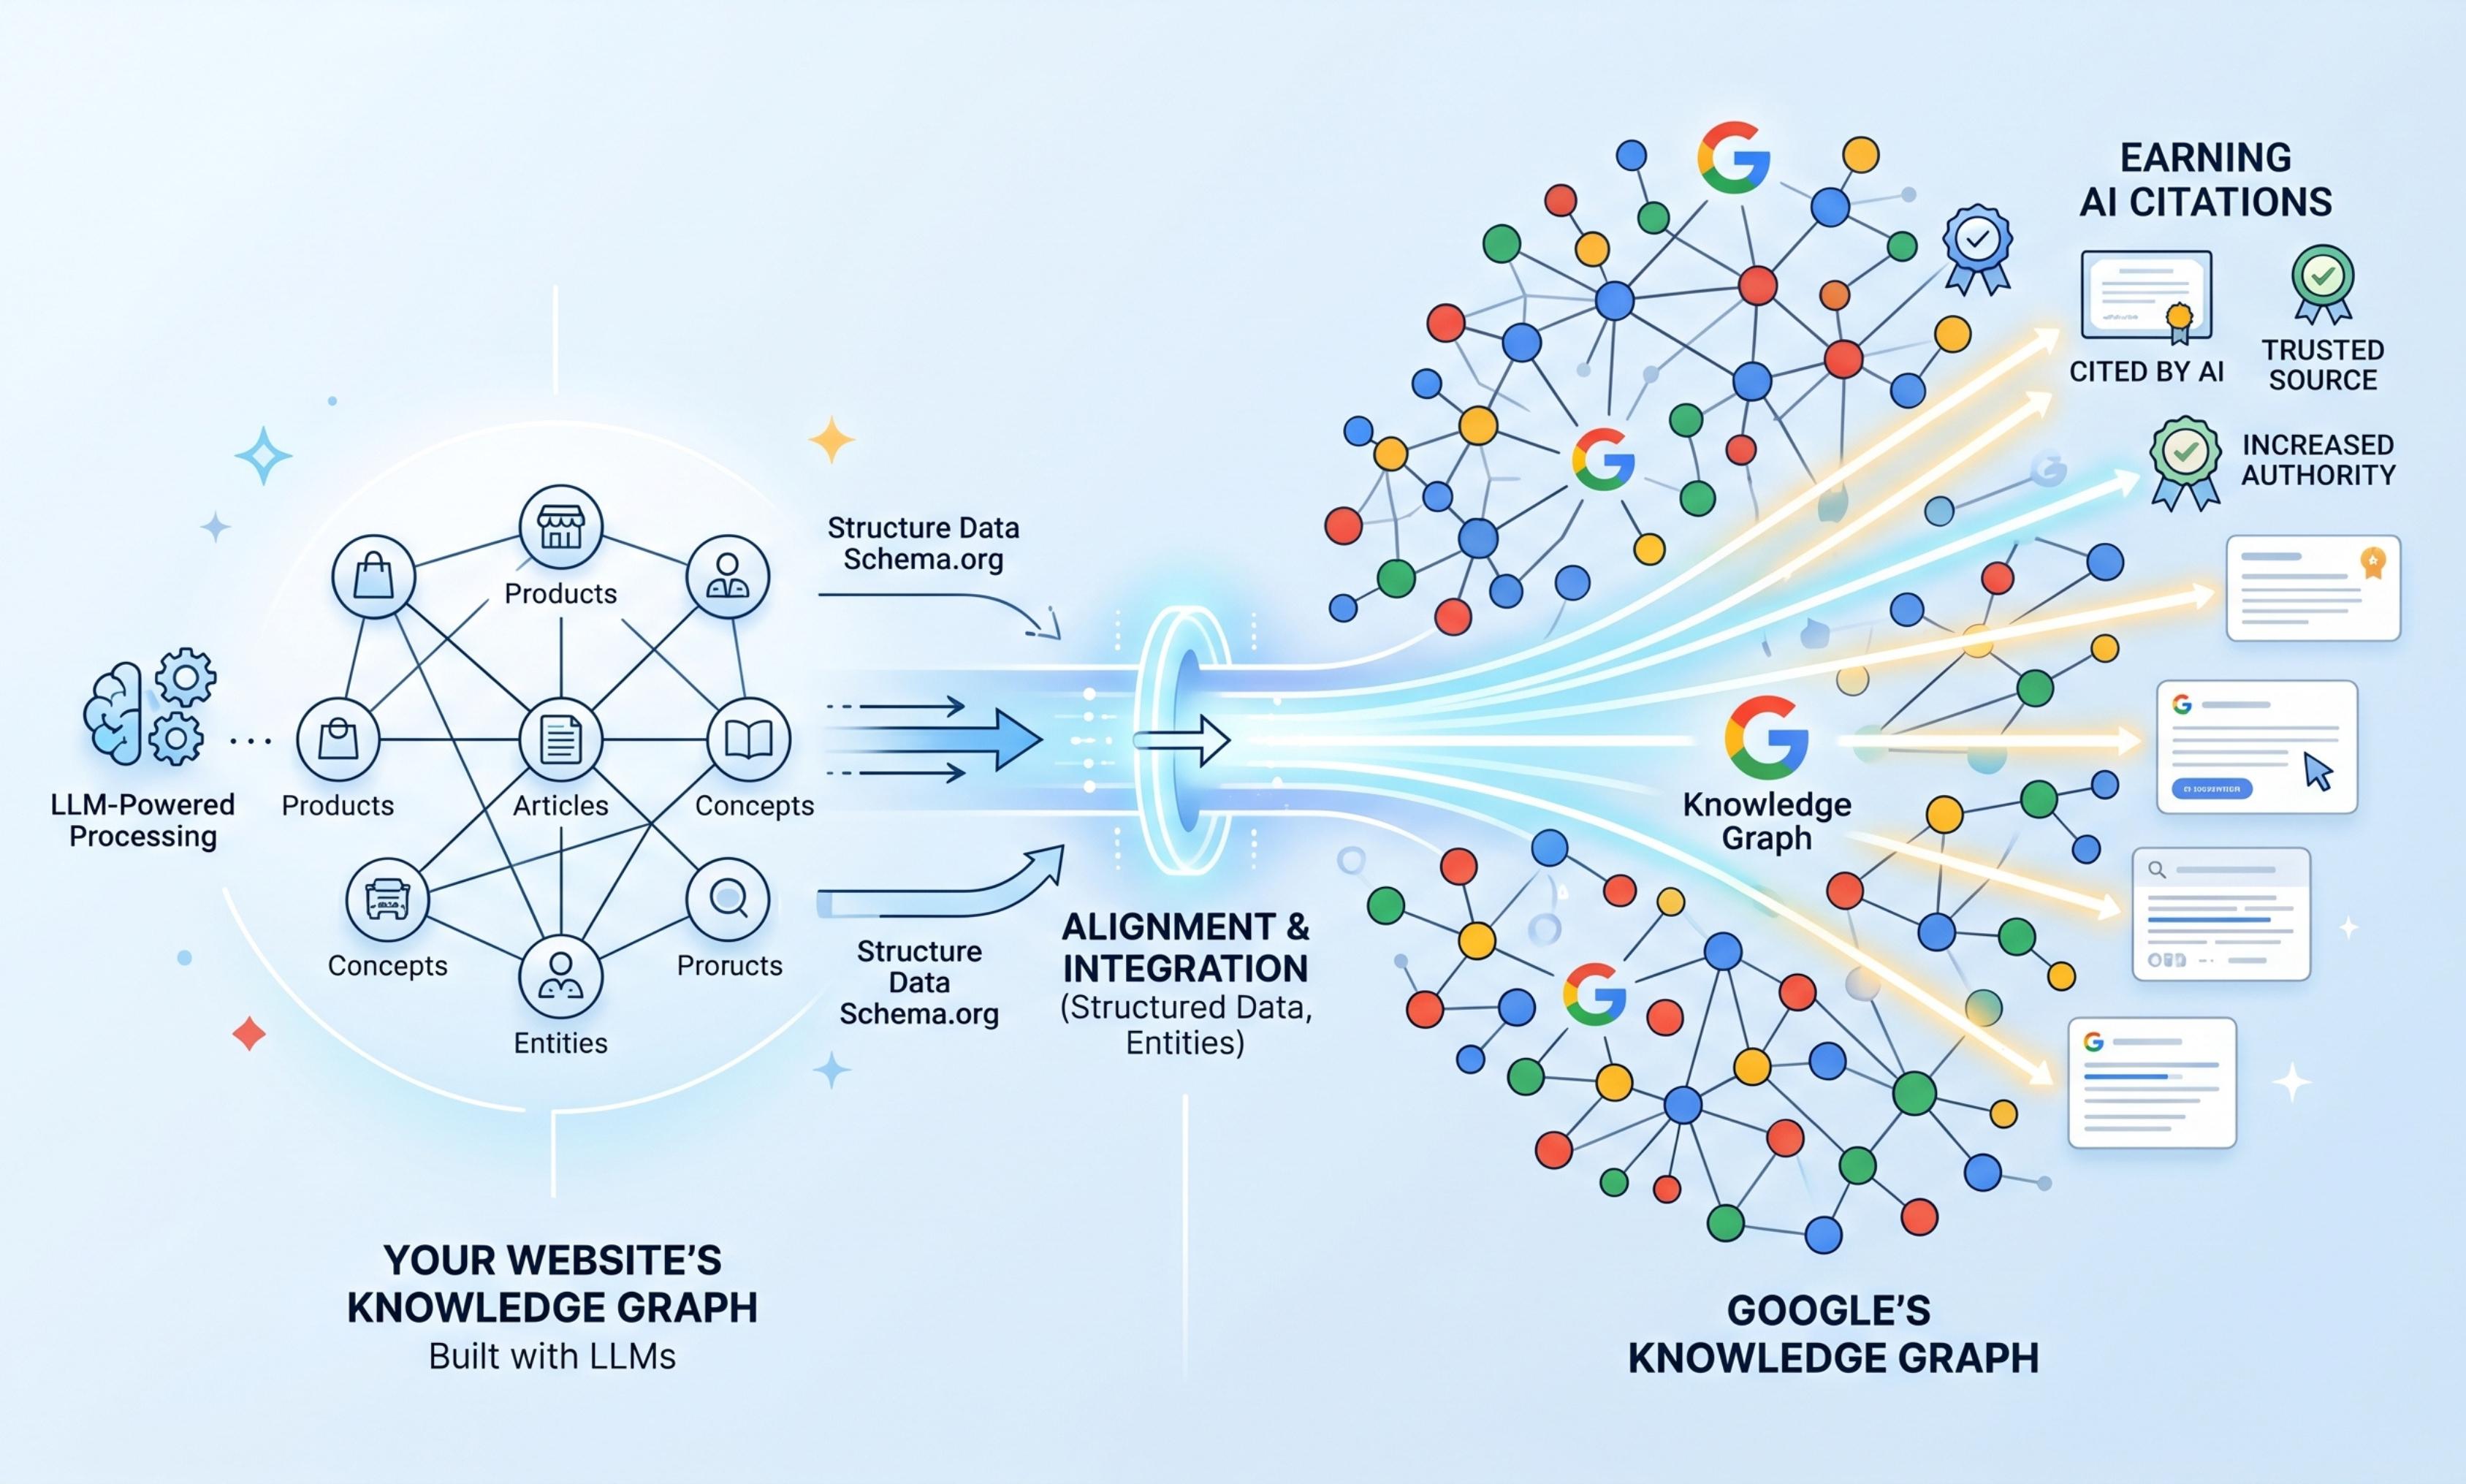
Now you turn your entity list and relationship map into machine-readable schema markup. This is where your website actually becomes a knowledge graph in the eyes of AI systems.
Why JSON-LD Is the Format That Wins
Schema markup can be implemented in three formats: Microdata, RDFa, and JSON-LD. JSON-LD is what Google, Bing, and every modern AI tool prefer, because it sits in a clean <script> tag in your HTML head and doesn’t depend on visible page elements. JSON-LD is the graph format AI systems actually want.
The Minimum Schema Set Every Site Needs
Implement these schema types across your site systematically. Each one corresponds to a node type in your knowledge graph:
| Schema Type | What It Defines | Where It Goes |
|---|---|---|
| Organization | Your brand entity, attributes, and sameAs links | Site-wide (homepage, footer, or shared template) |
| LocalBusiness | Physical locations with NAP and hours | Location-specific pages |
| Service | Each individual service you offer | Service pages |
| Product | Each product (especially for SaaS or ecommerce) | Product pages |
| Person | Leadership and authors with credentials | About, team, and author pages |
| Article | Blog posts with author, dates, and topic | Every blog post |
| FAQPage | Question-based content blocks | FAQ sections and dedicated FAQ pages |
Example: Organization Schema With sameAs Links
Here’s what a properly structured Organization schema looks like for a service business:
{ "@context": "https://schema.org", "@type": "Organization", "@id": "https://yourdomain.com/#organization", "name": "Your Brand Name", "url": "https://yourdomain.com/", "logo": "https://yourdomain.com/logo.png", "founder": { "@type": "Person", "name": "Founder Name" }, "address": { "@type": "PostalAddress", "addressLocality": "City", "addressRegion": "State", "addressCountry": "US" }, "sameAs": [ "https://www.linkedin.com/company/yourbrand", "https://www.crunchbase.com/organization/yourbrand", "https://www.wikidata.org/wiki/Q12345", "https://twitter.com/yourbrand" ] }The @id is your entity’s permanent identifier on your site. The sameAs property links your entity to its corresponding pages on Wikidata, LinkedIn, and Crunchbase, telling AI tools “this is the same entity referenced over there.”
That single property is what consolidates your scattered web presence into one cohesive entity in the AI’s eyes.
Connect Your Schema Across Pages
The most common mistake we audit: brands implementing schema page-by-page without connecting any of it. Each page declares its own Organization schema, with different @id values, and AI tools see them as different organizations.
Fix this by:
- Using consistent @id values across every page (one ID per entity, sitewide)
- Using @id references in nested schema (e.g., a Service schema referencing the Organization’s @id)
- Validating with Google’s Rich Results Test on every release
- Running CI checks that block deploys with schema errors
A connected schema implementation is what transforms a stack of independent pages into a navigable knowledge graph.
Tools to Validate Your Markup
Don’t ship and pray. Validate everything:
- Google Rich Results Test: Confirms your markup is valid and eligible for rich results
- Schema.org Validator: General-purpose schema validation
- Schema App or Merkle Schema Generator: Connected schema platforms that prevent drift across pages
- Custom CI checks: Block deploys if schema breaks
💡 Pro tip: Don’t let LLMs auto-generate your schema markup page-by-page. They hallucinate properties, miss required fields, and create disconnected entities across your site. Use connected schema platforms or templated implementations instead.
How This Aligns With Google’s Knowledge Graph and Earns AI Citations
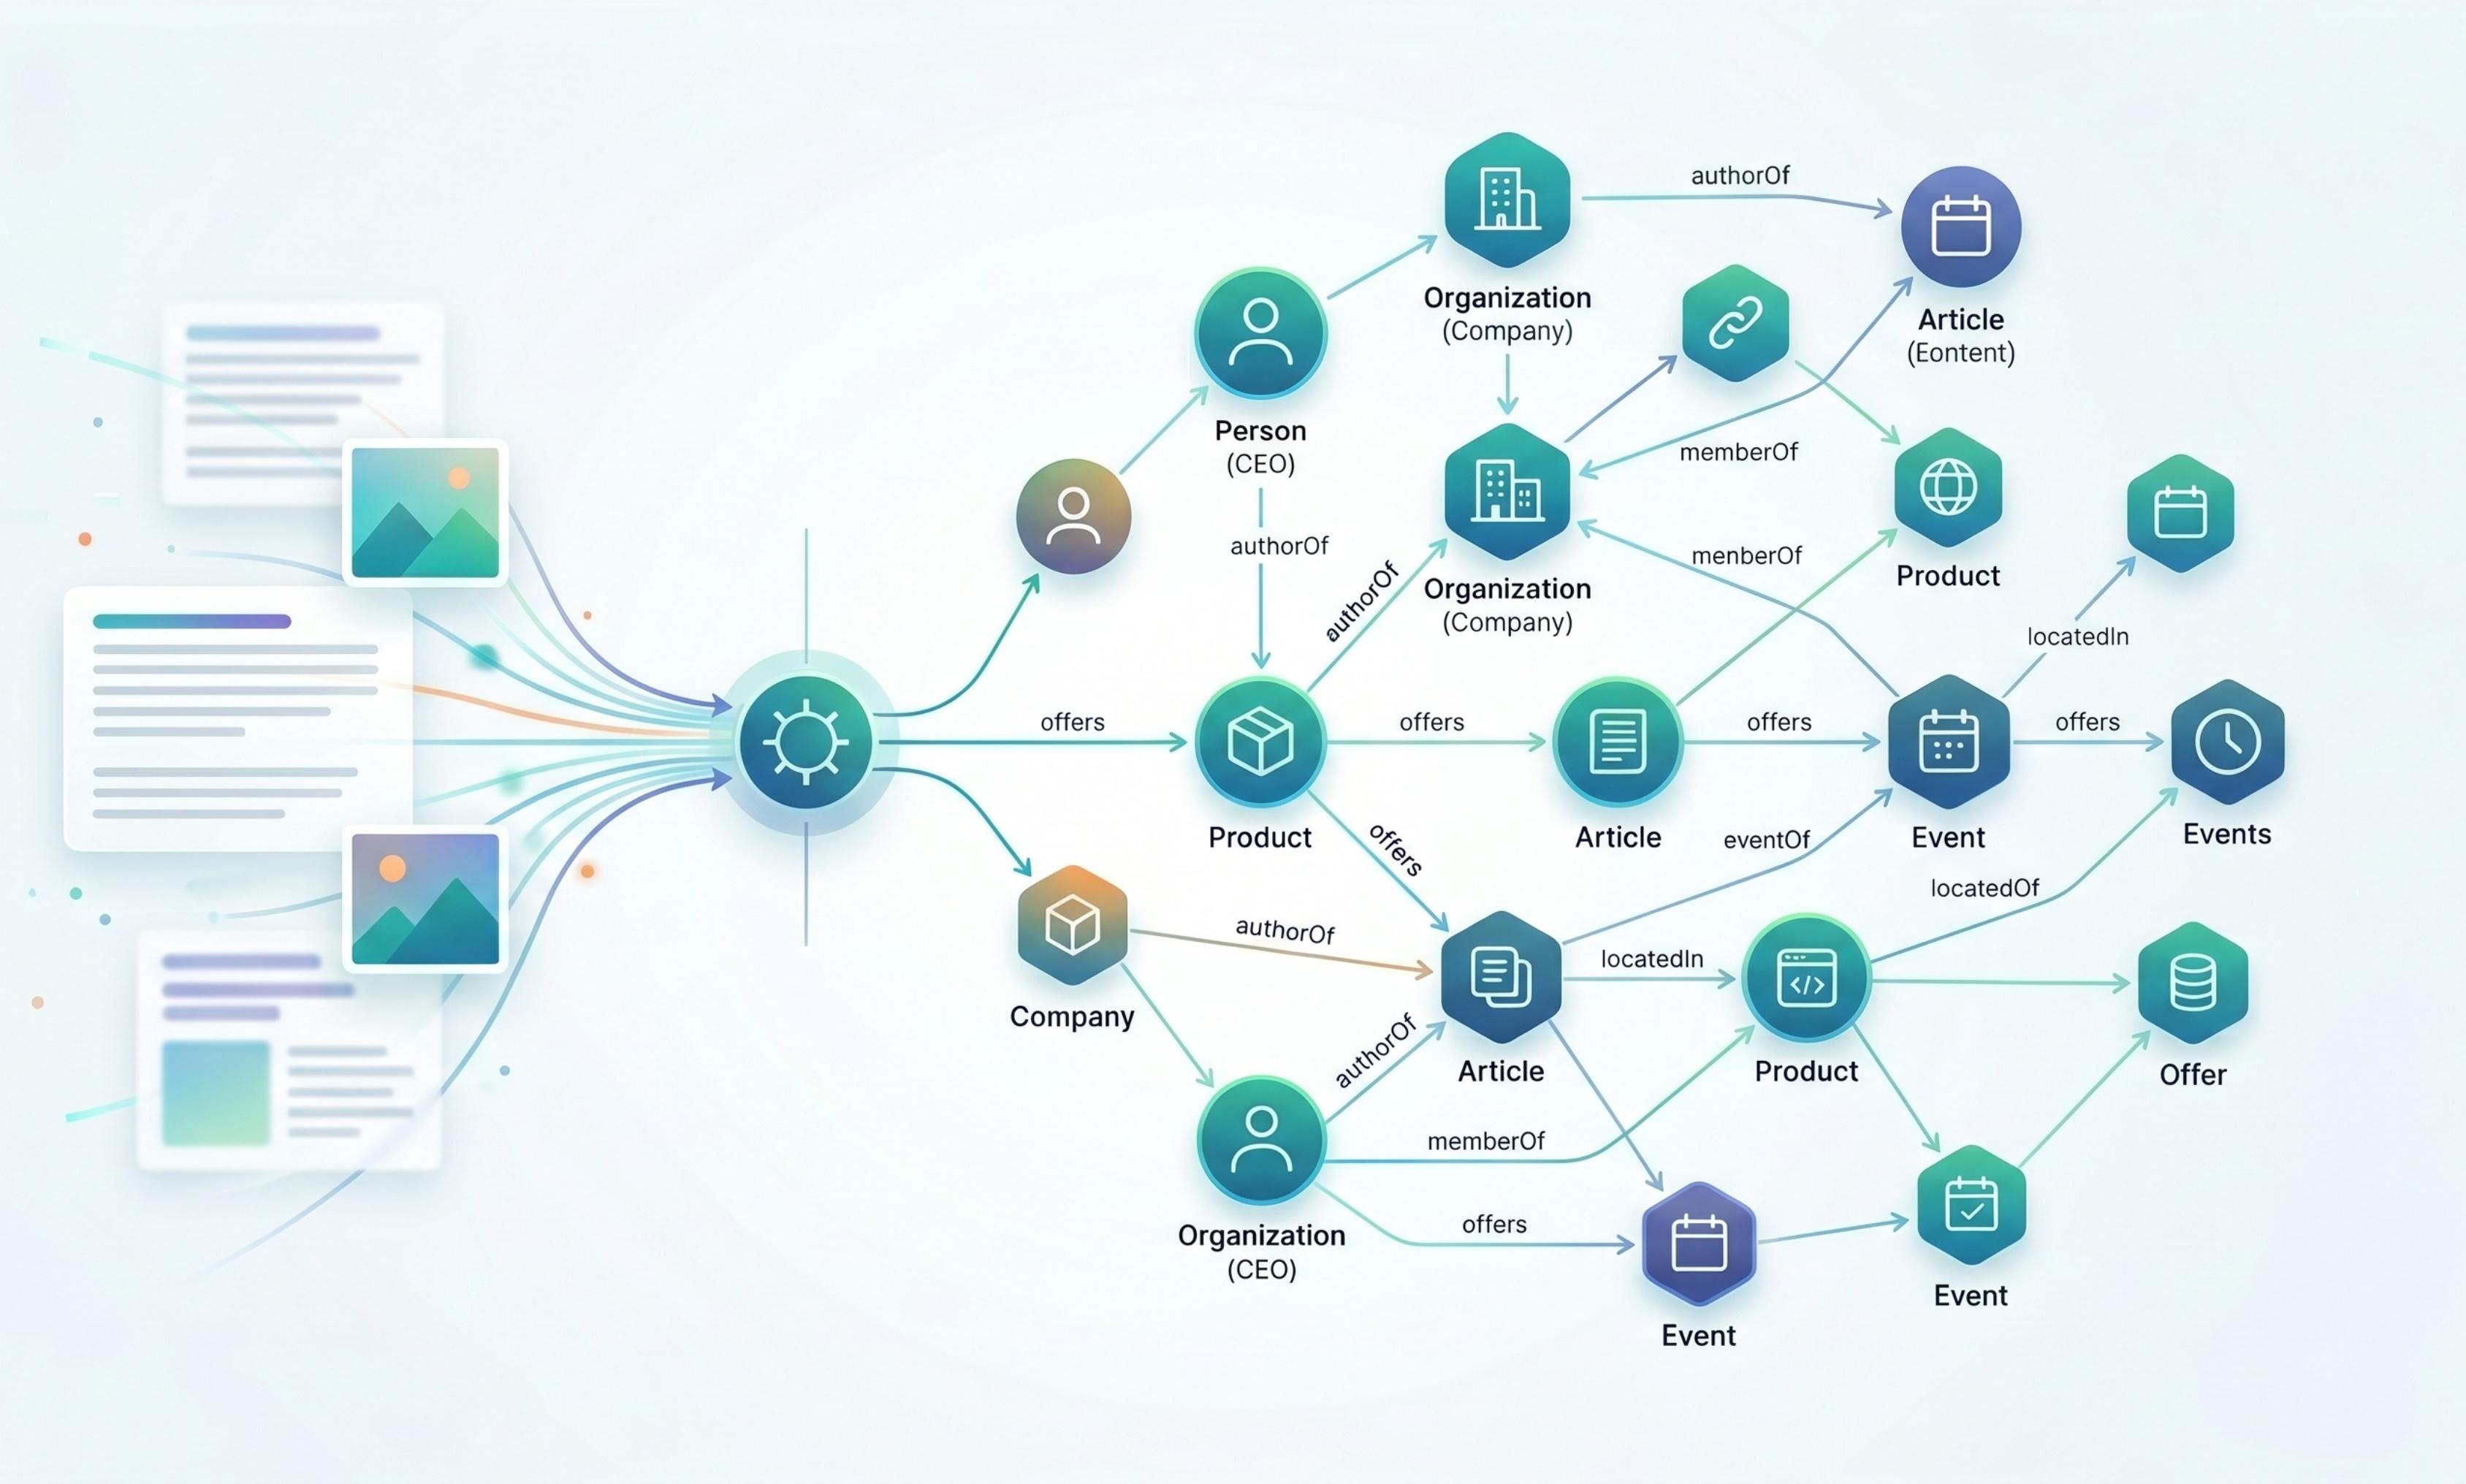
When your website is structured as a knowledge graph (entities extracted, relationships mapped, schema implemented), it aligns directly with how Google’s Knowledge Graph and modern AI systems organize their understanding of the world. That alignment is what unlocks AI citations.
The Bridge to Google’s Knowledge Graph
Google’s Knowledge Graph already contains hundreds of billions of facts about millions of entities. Your job isn’t to build a competing graph. It’s to make sure your entity is recognized and connected inside Google’s existing one.
Three signals connect your site to Google’s Knowledge Graph:
- Schema markup with sameAs links to authoritative external sources (Wikipedia, Wikidata, LinkedIn, Crunchbase, official social profiles)
- Consistent entity attributes across your website and external directories
- Clear topical authority demonstrated through interconnected content clusters covering related entities
When all three align, Google’s Knowledge Graph recognizes your brand as a defined entity with verified attributes. From there, your brand starts appearing in knowledge panels, AI Overviews, featured snippets, and traditional search results.
The Leap to AI Citations
Once your entity is recognized in Google’s Knowledge Graph, the AI search ecosystem amplifies the effect. Tools like ChatGPT, Gemini, Claude, and Perplexity all use knowledge graphs (sometimes Google’s, sometimes their own, sometimes Wikidata) to ground their answers.
A site structured as a knowledge graph is automatically more eligible for citation across all of them because:
- Disambiguation is easy. Your entity has stable IDs and sameAs links, so AI tools can identify you confidently.
- Multi-hop reasoning works. Your relationships let AI traverse your services, locations, and topics to answer complex questions.
- Trust signals stack. External sameAs references reinforce your entity across multiple data sources.
- Citations become natural. When AI tools generate an answer about your category, your structured site is the easy, low-risk source to cite.
The brands earning consistent citations across AI tools didn’t get there by accident. They got there by structuring their websites as knowledge graphs.
The 30-Day Implementation Roadmap
If you want to ship this end-to-end in 30 days, here’s the realistic schedule:
| Week | Focus | Deliverable |
|---|---|---|
| Week 1 | Entity extraction | Master list of entities, types, and Knowledge Graph IDs across your site |
| Week 2 | Relationship mapping | Subject-predicate-object triples for your top 50 pages and key entities |
| Week 3 | Schema implementation | Connected JSON-LD markup deployed across Organization, Service, Product, FAQPage, and Article schemas |
| Week 4 | Validation and submission | Rich Results Test on every page, Wikidata entry created or updated, top external profiles aligned with schema |
This isn’t a year-long project. It’s a focused month of work that transforms how AI systems perceive your brand.
Measure What Changes
After implementation, track these signals over the next 90 days:
- Knowledge panel appearances for your brand and key entities
- AI citation frequency across ChatGPT, Gemini, Claude, and Perplexity
- Branded search lift in Google Search Console
- AI referral traffic in your custom GA4 channel group
- Long-tail rankings you didn’t explicitly target
When all five climb together, your site is functioning as a knowledge graph in the eyes of AI systems. When some climb, and others stall, the gap reveals exactly where to focus next.
💡 Pro tip: Don’t expect day-one results. Schema and entity changes take 30 to 90 days to fully propagate through Google’s Knowledge Graph and the various AI training pipelines. Patience compounds. Brands that quit at day 30 miss the inflection point at day 60-90.
This is exactly the workflow our team ships for clients across SaaS SEO engagements, LLM SEO projects, and GEO agency work. The end-to-end transformation from “website” to “knowledge graph” is the highest-leverage move most brands can make in 2026, and it’s the one that compounds for years afterward.
The brands that engineer this now will own AI search visibility for the next decade. The ones that wait will spend that decade watching competitors get cited in every AI conversation in their category.
Common Questions and Edge Cases
The four-step playbook covers 80% of what most brands need. The other 20% is the edge cases, technical decisions, and “what if” scenarios that come up the moment you actually start implementing. Here’s what to know before you hit them.
Should You Use a Real Graph Database?
For most brands chasing AI visibility, the answer is no. A real graph database (Neo4j, TigerGraph, Memgraph) is heavyweight infrastructure designed for internal AI tools, recommendation systems, fraud detection, or enterprise analytics across diverse sources of data.
For SEO and AI search visibility, your “knowledge graph” lives inside your schema markup, content structure, and internal linking. You’re not running Cypher queries against your underlying data. You’re making your website behave like a knowledge graph for AI systems crawling it.
Consider a real graph database only if you need to:
- Power an internal AI assistant or chatbot
- Run pattern matching across millions of entities
- Build recommendation systems on user queries
- Support multi-hop graph traversal at scale
- Manage complex relationships across multiple data types
Otherwise, schema-as-graph is the right move.
Property Graphs vs. RDF: Which One Matters?
Two graph data models exist in the wild:
| Model | Examples | Best For |
|---|---|---|
| Property graphs | Neo4j, TigerGraph | Internal applications, flexible schemas |
| RDF/semantic web | Wikidata, DBpedia, schema.org | SEO, AI alignment, web-scale interoperability |
For brand visibility work, you only need to care about RDF data and schema.org. They’re the standards Google, Bing, and AI systems use. Property graphs are mostly internal infrastructure.
What About Vector Databases?
Vector databases (Pinecone, Weaviate, Qdrant, ChromaDB) store vector embeddings of your content for semantic search. They use cosine similarity and a vector index to find related content based on meaning rather than exact match.
You don’t need one for AI SEO. AI tools already operate their own vector indexes against your content. Your job is to make your text and schema clean enough for those vector embeddings to be useful.
If you’re building an internal AI tool, that’s different. There, you’ll often combine a knowledge graph (for explicit relationships) with a vector database (for semantic similarity). Same pattern as GraphRAG, just running on your own data.
How Do You Handle PDF Documents and Diverse Sources?
If your brand publishes PDF documents, whitepapers, internal documents, or content across diverse sources, AI systems may struggle to extract entities and relationships consistently. Two fixes:
- Convert critical PDFs to indexable HTML pages. This makes your knowledge base accessible to AI crawlers and full-text search.
- Run cleaning data routines on PDF content. Use tools like Adobe’s PDF extract API or Unstructured.io to convert data from PDFs into structured text before feeding it through entity recognition pipelines.
Brands with PDF-heavy archives often see massive AI visibility lifts just by converting their top PDFs to HTML and adding proper schema markup.
Where Should You Identify Key Entities and Relationships?
When you identify key entities and identify relationships, prioritize:
- Brand entity (the most important node)
- Top 5 to 10 services or products
- Top 5 to 10 industries served
- Top 5 to 10 locations
- Top 10 leadership and author entities
- Top 20 topical concepts you want to own
That’s roughly 50 to 80 entities, which is enough to build out a comprehensive knowledge graph for most B2B and SaaS sites without resource-intensive overengineering.
What’s the Smallest Useful Implementation?
If you only have time to ship one thing, ship the Organization schema with proper sameAs links. That single piece of structured data on your homepage can connect your brand to Wikidata, LinkedIn, and Crunchbase, immediately strengthening your representation in AI knowledge graphs.
A small dataset of high-quality entity signals beats a sprawling, half-implemented graph every time.
How Do You Handle Updates?
Knowledge graphs aren’t static. Your data ingestion process needs an update cadence:
- Quarterly: Refresh schema attributes, update modification dates, validate sameAs links still resolve
- When services change: Add new Service schema entries, update internal linking
- When leadership changes: Update Person schema and team pages
- When new content publishes: Add Article schema with proper entity references
Without updates, your knowledge graph drifts away from real-world scenarios, and AI systems lose confidence in your data.
What About Schema for Question-Based Content?
For FAQs and Q&A content, the FAQPage schema is the easy win. But there’s a smarter pattern most brands miss: structure your FAQ content with a clear prompt template format that AI tools can extract verbatim.
Each FAQ should have:
- A question phrased the way a real user would ask it (not how you’d write a heading)
- A direct answer in the first sentence
- 1 to 3 supporting sentences for context provided
- Optional internal links to relevant cluster pages
That format makes the entire FAQ block citation-ready. AI tools lift these blocks into AI Overviews more often than any other content type.
Can LLMs Help With Relationship Extraction?
Yes, large language models LLMs are genuinely useful for relationship extraction at scale. The pattern that works:
- Crawl your site to extract clean text
- Chunk it into 500-word segments with overlap
- Send each chunk to an LLM with a relationship extraction prompt template
- Capture the JSON output as subject-predicate-object triples
- Standardize entity names and node labels
- Use the output as your relationship map
This is the same workflow used in tools like Neo4j’s LLM Knowledge Graph Builder, just simplified for SEO purposes. You’re not building production infrastructure. You’re generating structured input for your schema markup.
How Do You Measure Response Quality?
Once your site is structured as a knowledge graph, measure response quality by running AI prompt tests across ChatGPT, Gemini, Claude, and Perplexity monthly. Track:
- Whether the AI correctly identifies your brand
- Whether it cites all the properties you’ve published in the schema
- Whether it surfaces the right pages for complex questions
- Whether it can retrieve information across your content clusters
When these signals climb together, your knowledge graph is working. When they stall, you’ve found the next gap to fix.
💡 Pro tip: Knowledge graph implementation isn’t fire-and-forget. The brands that compound advantage treat it as a quarterly discipline, just like reporting or content production. Set the cadence early or you’ll watch the gains drift away within 12 months.
If wiring all of this into your existing infrastructure feels overwhelming, that’s exactly where having a partner like Doc Digital SEM’s LLM SEO services earns its keep.
We ship the entire workflow (entity extraction, relationship mapping, connected schema, AI citation tracking) end to end, so your team gets a knowledge-graph-aligned site without burning six months of engineering time.
Build Your Website Knowledge Graph With Doc Digital SEM
Turning your website into a knowledge graph is the highest-leverage move SEO teams can make in 2026. The brands that ship this transformation become recognized entities that AI tools cite confidently. The ones that don’t stay invisible, no matter how much content they publish.
Here’s what to remember:
- A “knowledge graph for SEO” lives in your schema, content, and internal linking
- Step 1: Extract entities using LLMs and NLP APIs
- Step 2: Map relationships between services, locations, products, and content
- Step 3: Implement connected schema markup with sameAs links
- Step 4: Align with Google’s Knowledge Graph for compounding AI citations
Building a knowledge-graph-aligned website is technical, multi-layered, and easy to half-implement. Doc Digital SEM ships the entire workflow end to end.
Get your free AI visibility audit (valued at $1,500) or explore our LLM SEO services and become the entity AI systems cite by name.
FAQs
Can LLM generate a knowledge graph?
Yes. LLMs and machine learning models can build a knowledge graph by extracting entities and semantic relationships from text, surfacing hidden patterns and relevant information for AI systems.
How to optimize your website for LLMs?
Add schema markup, build connected internal links, and structure content as semantic relationships that AI tools can extract. Knowledge graphs provide the relevant nodes AI systems use to cite your brand.
Can LLMs read HTML?
Yes. LLMs read HTML directly. Clean semantic HTML, schema markup, and structured query patterns help LLMs identify key features and extract relevant information without rendering JavaScript.
How to generate a knowledge graph?
Run entity extraction, map semantic relationships, then load extracted data into schema markup or graph databases. Unlike relational databases, knowledge graph-based systems use a query language like SPARQL or Cypher.


