


When ChatGPT recommends a brand, when Perplexity cites a source, when Gemini answers a complex question with confidence, none of it comes from raw text alone. It comes from an LLM knowledge graph: a structured network of entities, relationships, and verified facts that AI systems use to retrieve, reason, and generate answers. If your brand isn’t represented inside these graphs, you’re invisible to the AI tools your buyers are already using.
GraphRAG, the technique that combines LLMs with knowledge graphs, has become the reference architecture for production AI systems in 2026. The brands earning consistent citations across ChatGPT, Gemini, Claude, and Perplexity aren’t just publishing content. They’re building entity footprints that LLM knowledge graphs can confidently parse, link, and surface.
Here’s what we’ll go through in detail:
- What an LLM knowledge graph actually is (the unified definition)
- How LLM knowledge graphs work behind AI search
- The difference between traditional knowledge graphs, vector databases, and LLM knowledge graphs
- How AI tools use LLM knowledge graphs to decide who gets cited
- How to make sure your brand appears inside the LLM knowledge graphs that matter
If this concept feels new, it should. Most agencies haven’t caught up yet. Doc Digital SEM has been building entity-rich, knowledge-graph-aligned foundations for clients across SaaS, healthcare, and B2B for over a year through our LLM SEO services and structured data implementation work, so brands stop hoping for AI visibility and start engineering it.
What Is an LLM Knowledge Graph
An LLM knowledge graph is a structured representation of entities, the relationships between them, and the verified facts that connect them, used by large language models to retrieve relevant information, reason across multiple data sources, and generate accurate, grounded answers.
That’s the formal definition. Here’s the plain-English version: it’s the map AI systems use to understand the world.
The Core Components
Every LLM knowledge graph has three building blocks:
| Component | What It Represents | Example |
|---|---|---|
| Nodes (entities) | Real-world things with stable identifiers | “Doc Digital SEM” (Organization) |
| Edges (relationships) | How entities connect to each other | “Doc Digital SEM” → provides → “LLM SEO” |
| Properties (attributes) | Verified facts about each entity | Founding year, leadership, locations served |
Together, these three components form a graph structure where every entity, every relationship, and every fact is explicitly linked. Unlike unstructured text, where meaning is inferred, an LLM knowledge graph has explicit relationships that AI systems can traverse, query, and trust.
Why It Matters
Large language models are trained on massive volumes of unstructured text. They’re powerful, but they hallucinate. They confuse entities. They miss connections. They can’t always remember what they learned during training versus what’s true today.
LLM knowledge graphs solve this by providing structured context that the model can reference at query time. Instead of relying purely on pattern recognition across billions of training data points, the LLM can pull specific entities, attributes, and relationships from the graph and ground its answer in verifiable facts.
The result: more accurate AI generated answers, fewer hallucinations, and consistent recommendations across queries.
Where LLM Knowledge Graphs Live
There’s no single, universal LLM knowledge graph. Different AI systems use different graphs:
- Public knowledge graphs like Wikidata, DBpedia, and Google’s Knowledge Graph
- Proprietary graphs maintained by Google, Microsoft, OpenAI, and other AI providers
- Domain-specific graphs for verticals like healthcare (medical knowledge graphs), finance, and legal
- Enterprise knowledge graphs built by companies on their own data
Most modern AI tools query multiple graphs simultaneously, plus their own training data, plus live web retrieval. The combination is what makes them powerful, and what makes brand visibility a multi-front game.
Knowledge Graphs and LLMs: The Basics
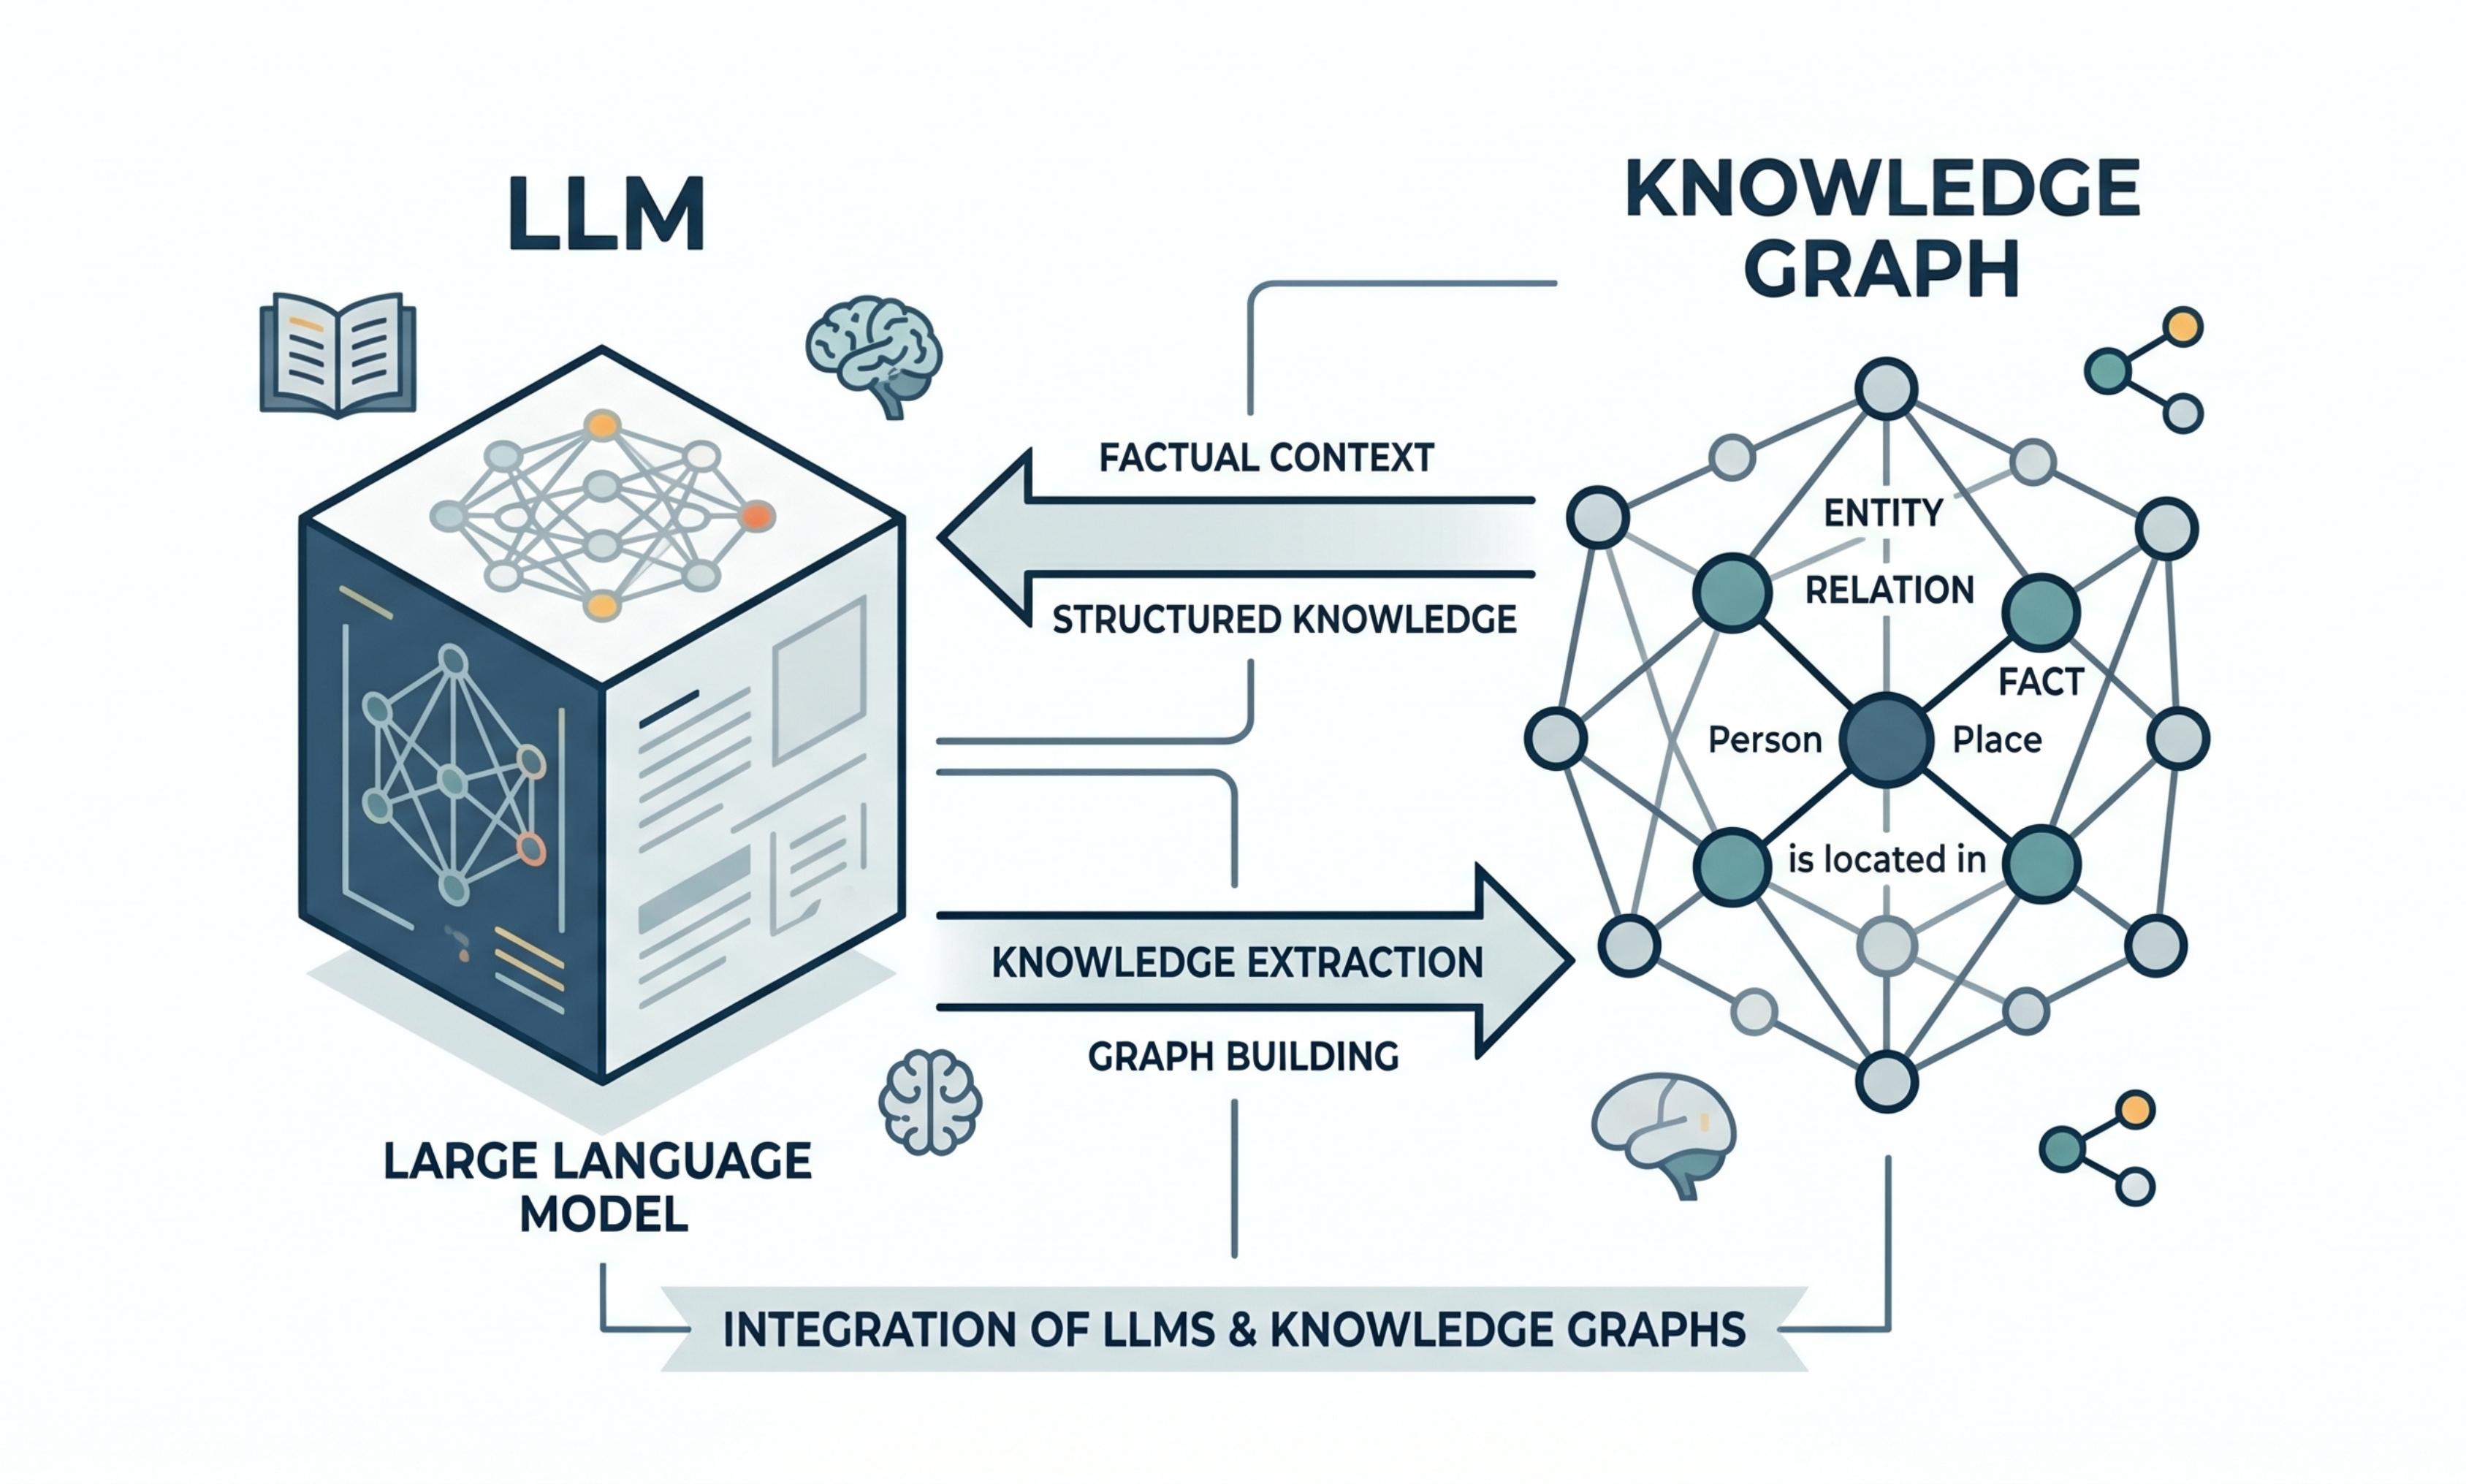
The term “LLM knowledge graph” gets thrown around loosely, and the confusion costs brands real visibility. Here’s the simple version every marketer should understand.
What “Knowledge Graph” Actually Means
A classic knowledge graph is a structured network of entities (people, places, things) and the explicit relationships between them. The most famous example is Google’s Knowledge Graph, which stores facts like:
- “Paris” → is the capital of → “France”
- “Elon Musk” → founded → “Tesla”
- “Apple Inc.” → is headquartered in → “Cupertino, California”
These facts are explicitly stored as nodes (entities) and edges (relationships). Neat, structured, and machine-readable. When Google shows you a knowledge panel, that data is coming straight from this graph.
Do LLMs Have One Built In?
Large language models like ChatGPT and Gemini don’t have a fixed, explicit knowledge graph stored inside them. They work differently.
1. Implicit Knowledge (Inside the Model)
During training, LLMs learn patterns and relationships between words and concepts. That knowledge gets compressed into the model’s neural weights, not stored as clean nodes and edges. The model understands that Paris is the capital of France, but it doesn’t have a row in a database that says so.
Think of it as a compressed, fuzzy knowledge graph hidden in math. The model can reason about entity relationships, but the relationships themselves aren’t stored anywhere you can point to.
2. Retrieval + External Graphs (Modern Systems)
This is where it gets interesting for AI SEO. Modern AI tools don’t rely on internal knowledge alone. They combine LLMs with:
- Structured databases
- APIs and live retrieval
- Actual external knowledge graphs (Wikidata, Google’s Knowledge Graph, etc.)
Examples:
- Google AI Overviews = Gemini + Google’s Knowledge Graph + live web retrieval
- Microsoft Copilot = GPT-4 + Bing index + structured data
- Perplexity = LLM + live web search + cited sources
- Wikidata acts as an external graph that multiple AI tools query directly
The modern AI stack looks like this:
LLM (language reasoning) + Knowledge Graph (structured facts) + Retrieval (real-time data)
That hybrid is why modern AI tools can answer specific, factual questions confidently. The LLM handles reasoning. The knowledge graph provides verified facts. Retrieval keeps things current.
Why This Matters for AI SEO
LLMs don’t rely purely on their internal training anymore. They actively pull from structured sources, prefer clear entities and explicit relationships, and trust well-defined, connected data over vague text.
That’s exactly why:
- Schema markup is now critical
- Entity consistency across the web matters more than ever
- Knowledge graph presence (Wikidata, Crunchbase, LinkedIn) decides who gets cited
You’re not just trying to rank in search results anymore. You’re trying to become a recognized node in the AI’s ecosystem of trusted entities.
A Simple Analogy
If this still feels abstract, here’s the easiest way to think about it:
| Concept | Analogy |
|---|---|
| Traditional knowledge graph | A perfectly organized map |
| LLM | A brain that studied the map but doesn’t store it neatly |
| Modern AI system | A brain + a live GPS + an official map database, all working together |
The brain alone can guess. The brain, plus the live GPS, plus the official map can answer with confidence and cite the source.
The Bottom Line
Three things to walk away with:
- LLMs don’t have a traditional knowledge graph stored internally
- They do learn entity relationships during training, but in a fuzzy, compressed way
- Modern AI systems actively combine LLMs with real knowledge graphs to ground their answers
That third point is the one that decides whether your brand gets cited in 2026 and beyond. If you’re not represented in the knowledge graphs AI tools query, the LLM has nothing reliable to anchor its answer to. You disappear from the conversation.
How LLM Knowledge Graphs Work Behind AI Search
Understanding the mechanics is what separates brands that engineer AI visibility from brands that hope for it. Here’s what actually happens when an LLM uses a knowledge graph to answer a query.
The Six-Step Process
When a user asks an AI tool a question, the system runs a process that combines structured graph queries with generative language understanding:
- Parse the user’s query. The LLM identifies entities, intents, and constraints in the natural language input.
- Query the knowledge graph. The system retrieves relevant nodes (entities) and traverses the graph to find connected context.
- Retrieve supporting documents. Vector search or vector similarity pulls passages from unstructured text related to the entities found in the graph.
- Build structured context. The graph data plus retrieved passages form a custom corpus that the LLM can reason over.
- Generate the answer. The LLM synthesizes a response grounded in both the structured graph and the retrieved unstructured data.
- Cite the sources. The AI tool attributes its answer to the source documents and entities used in generation.
This combined approach (knowledge graph plus retrieval augmented generation) is the foundation of every modern AI search system. It’s why ChatGPT, Perplexity, Gemini, and Claude can answer complex queries that pure text retrieval alone could never handle.
The Power of Multi-Hop Reasoning
Knowledge graphs enable something traditional retrieval cannot: multi-hop reasoning. This is the AI’s ability to traverse multiple connections in the graph to answer layered questions.
Example query: “Which AI SEO agencies serve B2B SaaS companies in Florida and offer GEO services?”
To answer that, the system has to:
- Identify “AI SEO agency” as an entity type
- Filter to those serving “B2B SaaS”
- Filter further to those operating in “Florida”
- Filter again to those offering “GEO” (Generative Engine Optimization)
Each filter is a hop across the graph. Without explicit relationships in a knowledge graph, no LLM can reliably handle that kind of layered query. With one, multi-hop traversal returns a precise, well-defined answer.
How GraphRAG Changed the Game
In early 2024, Microsoft Research introduced GraphRAG, a technique that combines retrieval augmented generation with knowledge graph construction. GraphRAG operates in two phases: an offline indexing phase that builds the knowledge graph and community summaries, and an online query phase that uses them to answer questions.
The result: AI systems can answer broad, corpus-level questions (“What are the main themes across these 500 documents?”) and specific entity-level questions (“What does this company do?”) using the same underlying graph. That dual capability is why GraphRAG became the reference architecture for AI search infrastructure throughout 2025 and 2026.
💡 Pro tip: Most AI tools now blend GraphRAG-style architectures with their own retrieval layers. The brands that win citations are the ones structured for both graph-based queries (entity clarity, schema, sameAs links) and vector search (passage-level extractability and semantic similarity).
Knowledge Graphs vs. Vector Databases vs. LLM Knowledge Graphs
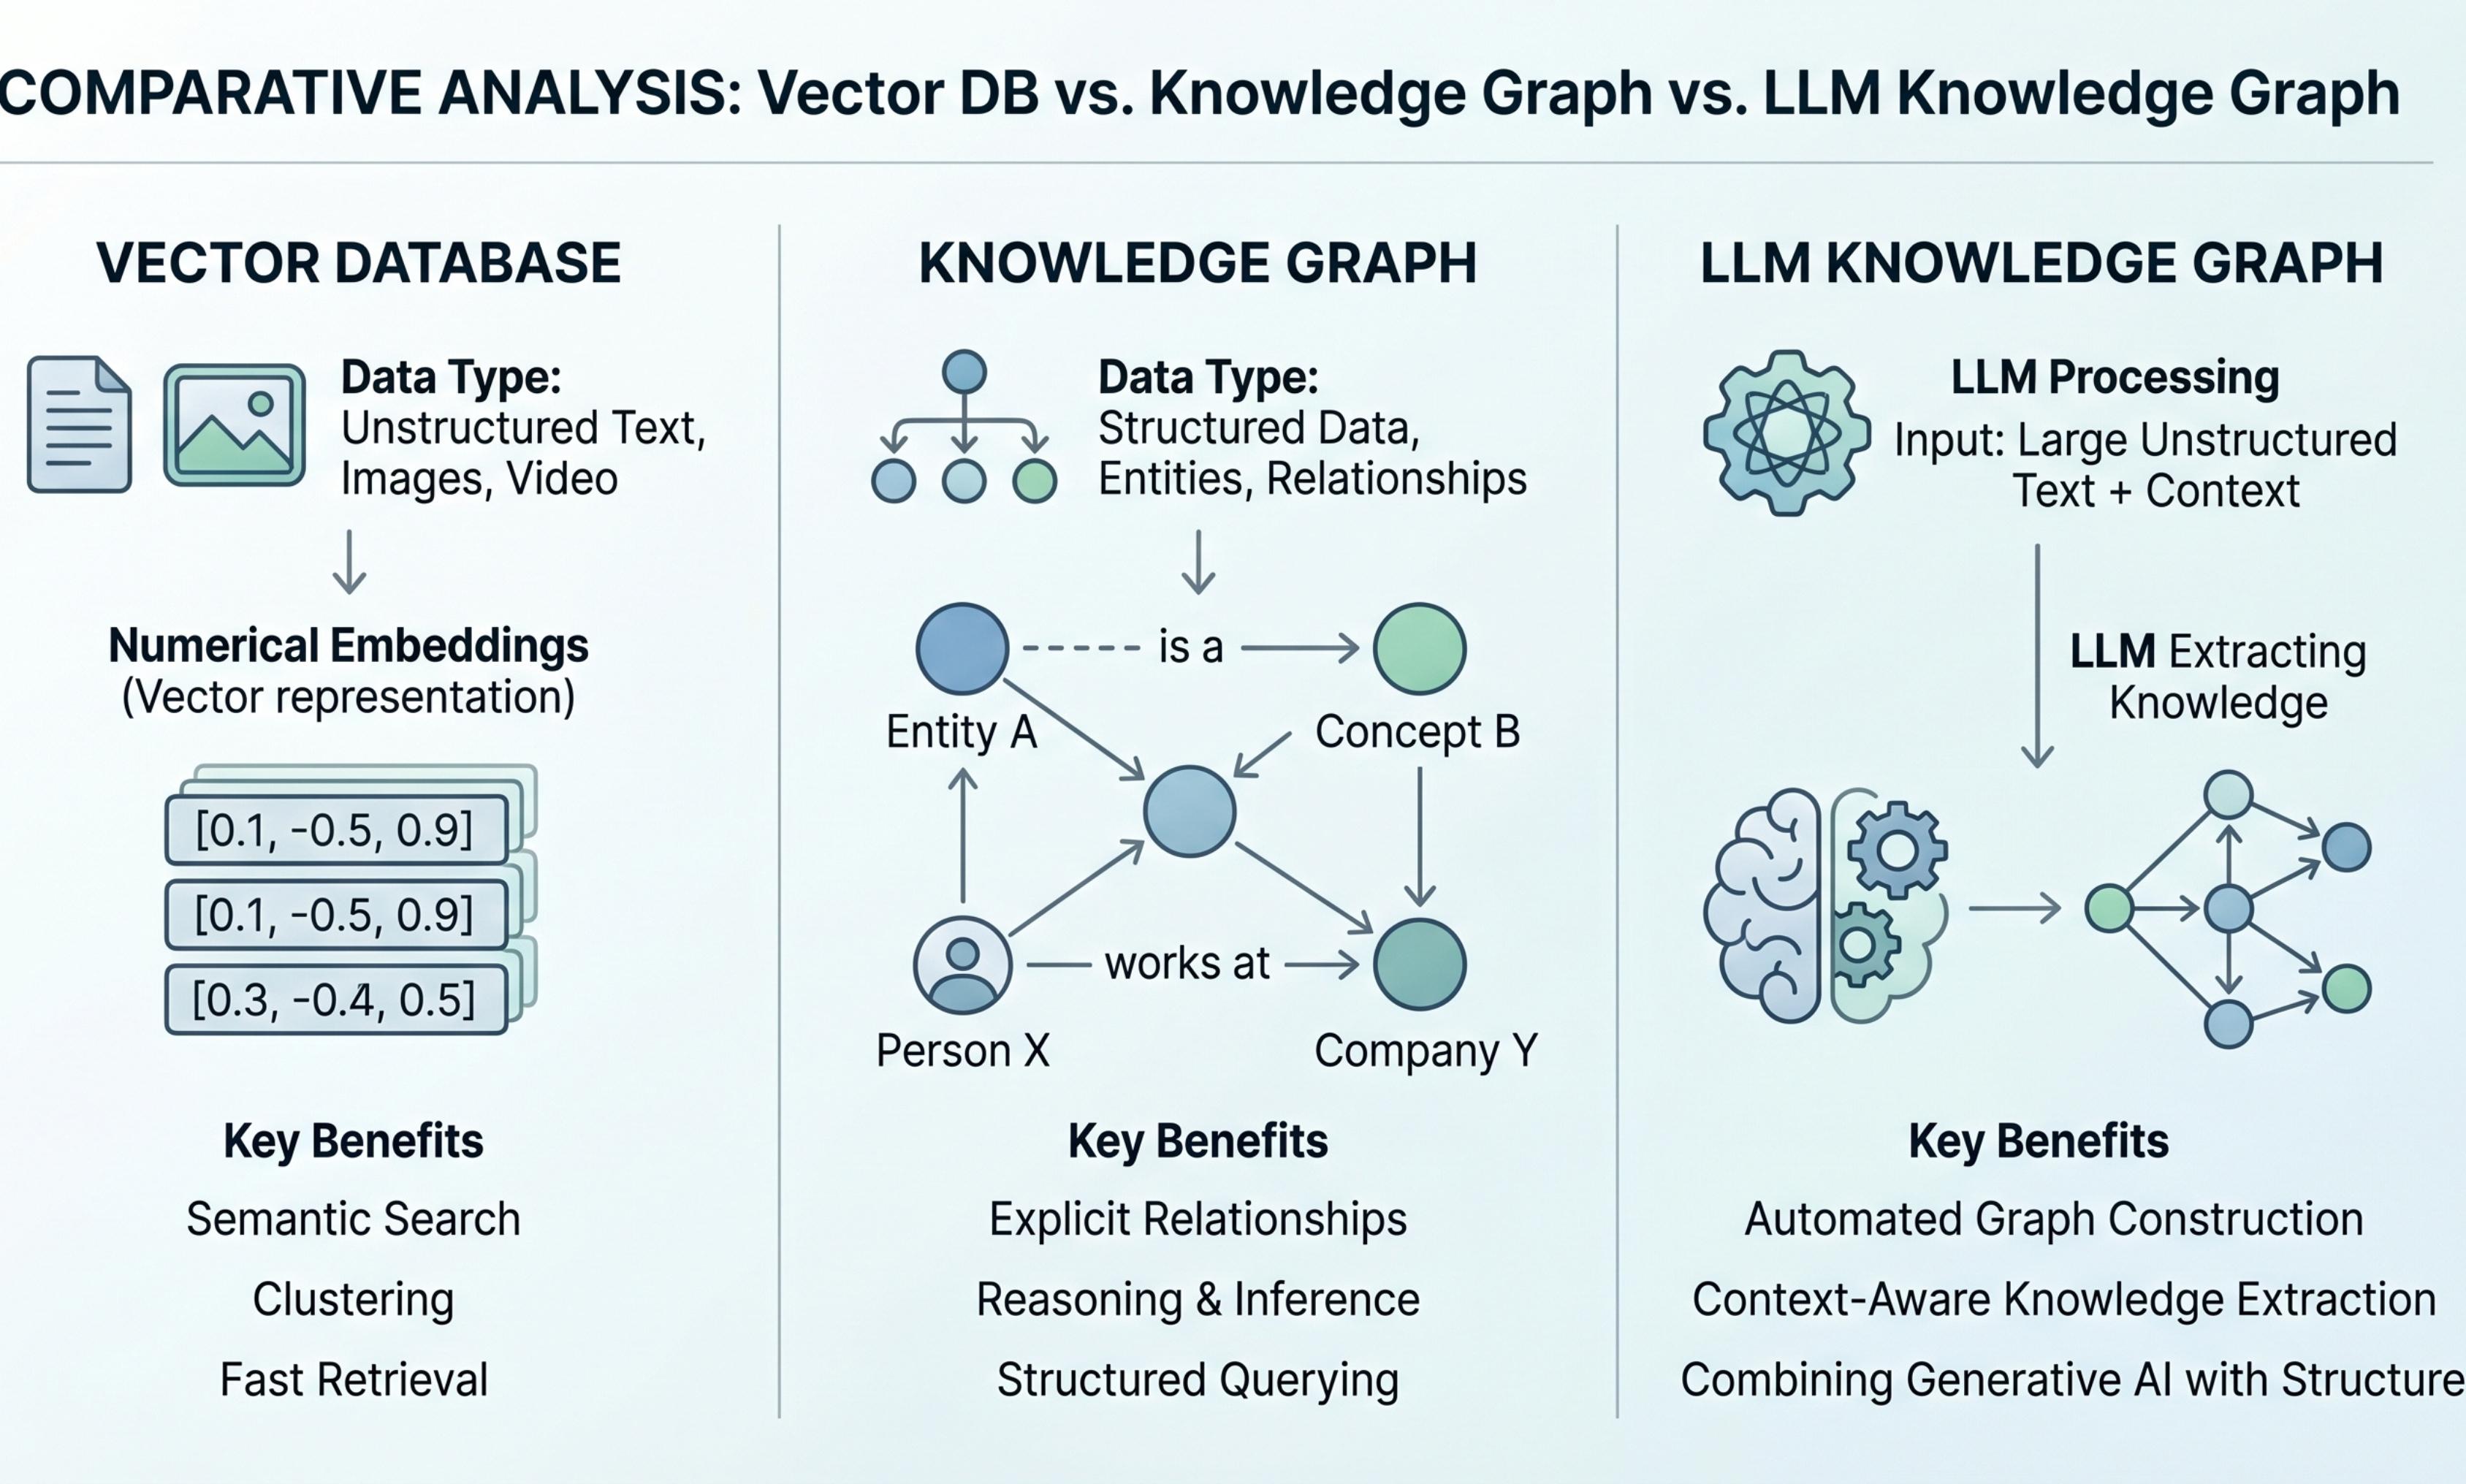
These three terms get conflated constantly. They’re related, but they’re not the same thing. Understanding the differences is what helps you make smart decisions about how to make your brand visible to AI.
The Three Approaches Side by Side
| Approach | What It Stores | How It Retrieves | Best For |
|---|---|---|---|
| Traditional knowledge graphs | Entities, relationships, attributes (structured graph data) | Structured queries (SPARQL, Cypher) and graph traversal | Multi-hop reasoning, complex relationships, and domain-specific applications |
| Vector databases | Embeddings of unstructured text and concepts | Vector similarity search (semantic similarity) | Semantic search across raw data, finding similar content |
| LLM knowledge graphs | Both structured entities/relationships AND vector embeddings | Hybrid graph queries plus vector search | Modern AI search, GraphRAG, complex queries with reasoning |
The big shift in 2025-2026 is hybrid architectures. Pure graph databases couldn’t handle the ambiguity of natural language queries. Pure vector databases couldn’t reliably traverse explicit relationships. LLM knowledge graphs combine both, making them ideal for AI tools that need to reason across enterprise data, customer data, and the open web simultaneously.
Why Hybrid Wins
Each approach alone has limits:
- Graph databases alone require rigid ontologies and miss the nuance of unstructured language. Schema is brittle. Maintenance is expensive.
- Vector search alone finds semantically similar content but can’t reliably traverse explicit relationships. It’s great for “find me articles like this one,” but terrible for “find me companies that serve X industry, in Y region, offering Z service.”
- LLM knowledge graphs combine the best of both. Structured graph queries handle multi-hop reasoning. Vector search handles fuzzy matches and semantic expansion. The LLM glues it all together with natural language understanding.
This is exactly why combining knowledge graphs with vector search produces the meaningful insights modern AI users have come to expect.
Where Brands Should Focus
Most marketers don’t need to build their own knowledge graph. What they need is to make sure their brand, products, and services are clearly represented inside the graphs AI tools already query.
That means:
- Showing up in public knowledge graphs (Wikidata, Wikipedia, Crunchbase)
- Aligning your schema markup with knowledge graph standards
- Building consistent entity footprints across the web
- Earning mentions on sources AI tools actively pull from
Brand visibility in 2026 is less about building a knowledge graph than about getting represented in the ones AI systems already use. Our LLM SEO services are built specifically around this work. We get your brand into the graphs that matter, then keep it there.
How AI Tools Use Knowledge Graphs to Decide Who Gets Cited
Every time an AI tool generates an answer, it’s making a series of decisions about which brands, products, and sources to include. Knowledge graphs are how it makes those decisions.
The Citation Decision Process
When ChatGPT, Gemini, Claude, or Perplexity decides which brand to cite, the LLM knowledge graph plays a crucial role at three stages:
- Disambiguation. When a query references an ambiguous entity (“Apple” the company vs. the fruit), the graph resolves which one based on context.
- Eligibility filtering. The graph filters out entities that don’t match the query’s constraints (industry, location, service type, customer segment).
- Authority ranking. Entities with stronger graph signals (more relationships, more verified attributes, more authoritative sources) rank higher in the candidate set.
Each stage eliminates potential brands. The brands that survive all three stages are the ones the AI cites.
What Gives a Brand Strong Graph Signals
Five factors determine how strongly your brand is represented inside LLM knowledge graphs:
- Canonical identifiers. Stable entity IDs in Wikidata, Knowledge Graph MIDs, organization identifiers, product GTINs
- Cross-source corroboration. Consistent mentions across Wikipedia, Crunchbase, LinkedIn, industry directories, and review platforms
- Schema markup with sameAs links. Telling AI systems explicitly that your entity is the same one referenced on Wikidata, LinkedIn, etc.
- Topic associations. Clear connections between your brand and the topics, services, or industries you want to be known for
- Recency. Recently updated facts and content signal that the entity is still active and relevant
Brands strong on all five get cited consistently. Brands weak on three or more get filtered out before the AI ever considers them.
Why Some Brands Get Skipped
The most common reasons we audit brands invisible in AI:
- No entity ID across public knowledge graphs
- Inconsistent brand information (name, address, services) across the web
- Missing or incorrect schema markup
- Strong website, but no off-site validation
- Outdated facts that haven’t been refreshed in 18+ months
Each of these issues weakens your representation in the LLM knowledge graphs AI tools query. Each fix strengthens it. The math is straightforward.
📊 Worth knowing: AI tools weight third-party validation heavily because LLM knowledge graphs are designed to reduce hallucination by triangulating across multiple data sources. A brand that only exists on its own website looks unverified to AI, regardless of content quality.
For a deeper read on this topic, our breakdown on AI citations covers exactly how AI tools decide who to cite and why.
How to Make Your Brand Appear in LLM Knowledge Graphs
Knowing how LLM knowledge graphs work is academic. Getting your brand inside them is the actual work. Here’s the practical playbook our team applies to every client engagement.
Step 1: Establish Your Entity in Public Knowledge Graphs
Public knowledge graphs are the foundation. AI tools pull from them constantly, and presence here is the single fastest way to earn graph-level visibility.
Priorities:
- Wikipedia (where genuinely warranted by notability)
- Wikidata (an entry with key entities, attributes, and sameAs links)
- Crunchbase (founding info, funding, leadership, locations)
- LinkedIn (Organization page with verified info)
- Industry directories (G2, Capterra, Clutch for service businesses)
Each of these signals contributes to how confidently AI systems can identify and link your brand inside their LLM knowledge graphs.
Step 2: Implement Knowledge-Graph-Aligned Schema
Schema markup is how you tell AI systems what your brand is and how it connects to known entities. The minimum implementation:
- Organization schema with @id and sameAs links to Wikipedia, Wikidata, LinkedIn, and Crunchbase
- Service schema for each major service offering
- Product schema for each product, including identifiers like SKU or GTIN where applicable
- Person schema for leadership and authors with verifiable credentials
- LocalBusiness schema for any physical locations
The sameAs property is critical. It tells AI systems “this entity is the same one referenced over there,” collapsing potential ambiguity into a clean canonical match.
Step 3: Build Out Topic and Relationship Signals
LLM knowledge graphs care about relationships, not just entities. Your brand needs explicit connections to the topics, industries, and use cases you want to be known for. Build them through:
- Topic clusters that establish your authority on specific subjects
- Internal linking that signals topical relationships across your site
- Content explicitly mentioning related entities (industries served, integrations, partners, customer types)
- External coverage that mentions your brand alongside the topics you want to own
Each of these signals adds an edge to the graph, reinforcing the connections AI systems use to decide who to cite.
Step 4: Earn Cross-Source Corroboration
LLM knowledge graphs reduce hallucination by triangulating across multiple sources. To win this triangulation, you need consistent representation across:
- Industry publications and news media
- Reddit, Quora, and category-specific forums
- Podcast appearances and guest articles
- Review platforms relevant to your category
- Social profiles with consistent NAP and entity descriptions
The brands with the strongest LLM knowledge graph signals don’t have one massive website. They have a coherent brand presence across dozens of trusted touchpoints, all reinforcing the same entity.
Step 5: Maintain and Refresh
LLM knowledge graphs are dynamic. They update. Information changes. Your representation can drift over time as services evolve, leadership rotates, and new offerings launch.
Quarterly maintenance:
- Update Wikidata, Crunchbase, and LinkedIn with current information
- Refresh schema markup whenever services or attributes change
- Validate sameAs links still resolve correctly
- Track new mentions and ensure consistency
- Run AI prompt tests across ChatGPT, Gemini, Claude, and Perplexity to verify how AI tools are currently describing your brand
This isn’t optional. The brands with the strongest LLM knowledge graph presence are the ones treating their entity model as a living asset, not a one-time setup.
Step 6: Measure What’s Actually Happening
You can’t optimize what you don’t measure. The metrics that matter:
| Metric | What It Tells You |
|---|---|
| Knowledge panel appearances | Whether Google’s Knowledge Graph recognizes you |
| AI citation frequency | How often ChatGPT, Gemini, Claude, and Perplexity cite you |
| Brand description accuracy | Whether AI tools describe you correctly |
| Topical association strength | What topics AI tools associate with your brand |
| Cross-platform consistency | Whether different AI tools describe you the same way |
Track these monthly. The trends reveal whether your knowledge graph footprint is growing, stable, or shrinking. And they tell you exactly where to focus your next quarter of work.
💡 Pro tip: If your brand is described differently across ChatGPT, Gemini, Claude, and Perplexity, that’s a signal of inconsistent graph representation. Find the source of the inconsistency (usually Wikipedia, an outdated directory listing, or an old press release) and fix it. Consistency compounds quickly.
This is exactly the work we ship across every LLM SEO engagement, AI search optimization project, and structured data implementation we deliver. Knowledge graph presence isn’t a side feature. It’s the foundation everything else builds on.
The brand’s engineering for LLM knowledge graph visibility now will own AI search visibility for the next decade. The ones still treating it as a “future trend” will spend that decade wondering why their content keeps getting passed over.
Building Your Own LLM Knowledge Graph (For Teams That Need One)
Most brands are best served by getting represented inside the public LLM knowledge graphs that AI tools already query. But some teams need their own knowledge graph, especially in enterprise AI, SaaS platforms, and domain-specific applications where proprietary data, customer data, or internal workflows demand a private graph. If that’s you, here’s what the work actually involves.
When You Actually Need Your Own LLM Knowledge Graph
Building knowledge graphs is genuinely hard. Don’t take it on unless you have one of these use cases:
- Internal AI assistants that need to retrieve relevant information from proprietary data and unstructured text
- Customer-facing chatbots that need access to product catalogs, support docs, and usage patterns
- Enterprise search across multiple documents, departments, and access control layers
- Domain-specific applications like medical, legal, or financial AI tools, where public graphs lack the depth you need
- GraphRAG-powered SaaS features built on top of your own data pipelines
If your goal is brand visibility in ChatGPT and Perplexity, you don’t need to build a knowledge graph. You need to get into the existing ones.
The Five Stages of Knowledge Graph Construction
Here’s the standard pipeline for graph construction, simplified for non-engineers:
| Stage | What Happens | Why It Matters |
|---|---|---|
| 1. Schema design | Define entity types, relationship types, and attributes (the ontology) | Without a clear graph format, your data won’t connect cleanly |
| 2. Entity extraction | Pull entities from your raw data and unstructured text using NER and LLMs | This is where you extract entities from documents, transcripts, and emails |
| 3. Relationship inference | Identify how entities connect (the edges of the graph) | This is what enables multi-hop reasoning later |
| 4. Graph storage | Load the graph into a graph database (Neo4j, TigerGraph, Memgraph) | Storage architecture decides how fast structured queries return |
| 5. Query and retrieval | Build natural language interfaces, structured graph queries, and RAG pipelines | This is what makes the graph actually useful for users and AI agents |
Each stage has its own trade-offs and tooling decisions. Most teams underestimate stages 2 and 3, which is where the cumulative error propagation that derails LLM knowledge graph projects usually hides.
Key Features to Look For in a Graph Stack
If you’re evaluating tooling, these key features separate production-ready stacks from prototypes:
- GraphRAG support (retrieval augmented generation RAG built on top of graph traversal)
- Hybrid retrieval combining structured query and vector search
- Real-time updates so the graph reflects changes in your underlying training data
- Access control at the entity, relationship, and attribute level
- Graph analytics for finding patterns and meaningful insights across the entire dataset
- Native integration with LLMs through APIs or SDKs
- Schema flexibility that lets you evolve your ontology without rebuilding from scratch
Microsoft’s GraphRAG library, Memgraph, TigerGraph, Neo4j with LangChain, and Databricks’ graph offerings are all worth evaluating depending on your use case and existing data infrastructure.
Key Challenges Most Teams Hit
Five challenges trip up nearly every team building their first LLM knowledge graph:
- Schema rigidity. Designing a too-narrow an ontology that breaks when new entity types emerge.
- Entity disambiguation. Deciding whether “John Smith” the engineer and “John Smith” the customer are the same person across multiple data sources.
- Cumulative error propagation. Errors at the entity extraction stage compound through every downstream query.
- Context window limits. LLMs can only handle so much context at query time. Knowing what to load matters.
- Maintenance overhead. Keeping the graph fresh as data, entities, and relationships evolve.
The teams that solve these challenges treat their LLM knowledge graph like a living product, not a one-time engineering project. Continuous refinement, versioning, and governance are non-negotiable.
What Modern Approaches Get Right
The latest wave of LLM-powered knowledge graph approaches handles these challenges differently than rule-based systems of the past. Modern graph construction uses LLMs themselves to:
- Extract entities and relationships from unstructured text at scale
- Infer relational context, AI systems need for accurate reasoning
- Generate community summaries that compress meaningful insights from large corpora
- Build connected context across multiple documents without rigid ontologies
- Update the graph dynamically as new real-world data flows in
This is why GraphRAG and its successors (LazyGraphRAG, agentic RAG) have moved knowledge graph construction from a year-long enterprise project to a process teams can run on internal data within weeks.
The Marketer’s Decision Tree
If you’re a marketer or SEO lead reading this section, here’s the simple decision framework:
- Brand visibility goal? Don’t build. Get represented in public knowledge graphs through entity SEO, schema, and external corroboration.
- Internal AI tool goal? Consider building, but only after evaluating GraphRAG-based open-source tools first.
- SaaS product feature goal? Build, with experienced engineering. The graph becomes core infrastructure for your product.
- Enterprise search or knowledge management? Build, but partner with a graph specialist. The compliance, access control, and integration work is heavier than it looks.
For the brand visibility goal (which covers most readers of this article), the work is about making sure your entity is well-represented in the LLM knowledge graphs already powering AI tools. That’s where Doc Digital SEM’s LLM SEO services and structured data implementation work focuses, since it’s the highest-ROI move for 95% of brands chasing AI visibility in 2026.
💡 Pro tip: Building your own LLM knowledge graph is a 9 to 18 month journey for most teams. Getting your brand into existing knowledge graphs is a 90-day project. Pick the right battle for your goals before committing budget.
Win AI Visibility With Doc Digital SEM
LLM knowledge graphs are the foundation of modern AI search. The brands that show up consistently in ChatGPT, Gemini, Claude, and Perplexity aren’t just publishing content. They’re engineered to be findable inside the graphs AI tools query every second.
Here’s what to remember:
- LLM knowledge graphs combine structured entities with vector search for grounded answers
- GraphRAG is the architecture powering most modern AI search systems
- Public knowledge graphs (Wikidata, Crunchbase, LinkedIn) feed AI directly
- Schema markup with sameAs links is the connective tissue that makes your brand recognizable
- Most brands need representation, not construction
Showing up inside the LLM knowledge graphs that decide AI citations is a discipline. Doc Digital SEM ships it for clients every day. Get your free AI visibility audit (valued at $1,500) or explore our LLM SEO services and start owning the entities AI tools actually trust.
FAQs
What is an LLM knowledge graph?
An LLM knowledge graph is a structured data network of entities, relationships, and facts used by large language models (LLMs) to retrieve relevant data and generate accurate answers.
How do knowledge graphs improve LLMs?
Integrating knowledge graphs improves reasoning capabilities, reduces hallucinations, and grounds responses in verified facts, enhancing large language models with structured context AI tools can trust.
What’s the difference between a knowledge graph and a vector database?
Knowledge graphs use structured data and explicit relationships. Vector databases use semantic similarity. Modern LLM systems combine both for accurate retrieval and reasoning.
Why are knowledge graphs important for enterprise AI?
They provide enterprise context, support access control, and let large language models LLMs reason across user preferences, customer data, and proprietary information securely.
Can my brand appear in an LLM knowledge graph?
Yes. Build presence in Wikidata, Wikipedia, Crunchbase, LinkedIn, and use schema markup with sameAs links so AI tools recognize your brand as a verified entity.


